Google shipped Tool Retrieval in the Gemini Interactions API on November 19, 2026, and it is the most copyable engineering change in this week's news pool. The post is by Lucia Loher, product manager for the Gemini API, and Nora Kassner, a research scientist at Google DeepMind. Read it for the mechanism, not the product.
The mechanism is two lines of configuration. You add a tool_search tool to your request and set defer_loading: true on the tools you want held back. Your agent keeps its whole tool library on standby. The model still sees the name and description of every deferred tool, so it knows what exists. The parameter schemas stay out of context until the model asks for one by name.
That is it. No index to build, no vector store to run, no hosting. Which is exactly why you should steal it, even if you never call Gemini.
The failure mode it addresses is the one every team with a large catalog already feels. Your tool list grew with the product, one integration at a time, and at some point the model stopped picking the right tool. People blamed the model. The model was fine. You handed it a 400-entry menu and asked it to read every page before ordering. I made this argument before in "Your Agent's Tool Descriptions Are Costing You 66% Accuracy," and the fix then was rewriting descriptions. This is the structural fix underneath that one.
THE PROBLEM IS THE SCHEMA, NOT THE MODEL
Google's own function calling documentation states the problem more bluntly than the blog post does: "Every function declaration you send is billed as input tokens on every request, and tool selection accuracy declines as the number of candidates grows. Once you pass roughly 20 to 30 tools, consider tool retrieval."
Twenty to thirty. That is Google's own threshold, in its own docs, and it should reframe how you read your catalog. Most production agents I see are at fifty to three hundred.
Now the arithmetic. Take a representative tool: a name, a one-line description, and a parameters object with seven fields. Serialized, that declaration ran 463 characters in my test, which is 115.75 tokens per tool on the standard four-characters-per-token estimate. The token figure is mine, not Google's, and a real tokenizer will move it a few percent either way.
Multiply it out. Two hundred tools times 115.75 tokens is 23,150 tokens before the user says a word, which is the exact product rather than a rounded 23,200. That is 23 system prompts sitting in front of every request, 11.6 percent of a 200,000 token window, and 2.3 percent of the one million token window that Gemini 4 Hydrogen advertises. Names plus descriptions for the same catalog come to about 7,200 tokens, a 3.2 times reduction.
Here is the part most writeups skip, because it kills the easy cost story. Gemini 4 Hydrogen input runs $1.50 per million tokens and its implicit context caching runs $0.075 per million. At the full input rate, 23,150 tokens of schema costs you $0.034725 per request, which is $34.73 per thousand requests. Put the same prefix behind a warm cache and it costs $0.0017 per request. The cache is twenty times cheaper than uncached input.
So deferral does not save real money on a catalog you already send every turn behind a warm cache. It saves money on schemas you never load at all, which is the long tail, and it saves attention and latency everywhere. The savings are concentrated in the tools you never touch, and the accuracy win is in the ones you do.
The market context is why the accounting has to be this precise. The Ramp AI Index, built from transaction data at more than 85,000 US companies, reports that total token spending rose 12.0 percent in the week ending November 15, 2026, measured against the week ending October 18, 2026, while total token volume rose 27.2 percent. Those two figures come from Ramp's AI Spend Management sample, which is API spend at connected providers and routers rather than Ramp's whole AI volume. The blended price per million tokens across OpenAI and Anthropic sits at $0.45, $0.38 for OpenAI and $0.50 for Anthropic. Ramp lead economist Ara Kharazian put the six-week token price decline at 21.2 percent. Volume is compounding faster than revenue. If your unit cost is going to fall, it falls because you built the harness, not because the vendor cut the price again.
HOW DEFERRAL ACTUALLY WORKS
Progressive disclosure is the whole idea, applied to a tool catalog. Names are cheap. Descriptions are moderately cheap. Schemas are expensive. Spend on the first two, retrieve the third on demand.
Inside a single server-side request, Google's flow is three steps: the model searches for a tool by name, the API loads that tool's schema, and the model emits the function call. All of it happens inside the same call, and every step shows up in the response under interaction.steps as a tool_search_call, a tool_search_result, and then the function_call. That last detail is worth more than it looks. You can read exactly which tools the model considered and which ones it pulled a schema for, which turns tool selection debugging from guesswork into reading a log.
The cold-start penalty people worry about is real but narrower than it sounds. On the server-side path there is no extra round trip. The penalty belongs to the client-side path, where you declare tool_search with execution: "client" and run the lookup yourself. Google says plainly that client-side retrieval "adds one round trip per search," and in exchange you get your own registry, your own embedding index, and per-user permission filtering, plus the ability to expose new tools mid-conversation when a user connects an integration. If you hold a permission model, that trade is probably worth it. If you do not, let Google run the search.
Two more mechanics matter for architecture review. Deferral composes with prefix caching, because deferred schemas stay out of the start of the prompt and load later in the conversation, so the cached prefix stays identical from turn to turn. And it composes with remote MCP servers: set defer_loading: true on an mcp_server tool and every tool that server exposes is loaded on demand, so you can attach a thousand-tool server without listing its tools one by one.
The billing rule is the one to put in front of finance. There is no separate charge for Tool Retrieval. Input and output tokens bill at standard rates. Turning on tool_search adds a small fixed block of input tokens, and each schema the model loads is billed as input for the rest of the conversation, exactly as if you had declared it up front. In Google's own words, you save tokens when "the schemas you never load outweigh the ones you do."
That is the entire economic argument, and it is a ratio on your own traffic, not a feature claim.
THE THREE LEVELS OF DISCLOSURE, MEASURED
Every deferral design collapses to three levels, and you should test all three on your own catalog rather than trusting anyone's blog.
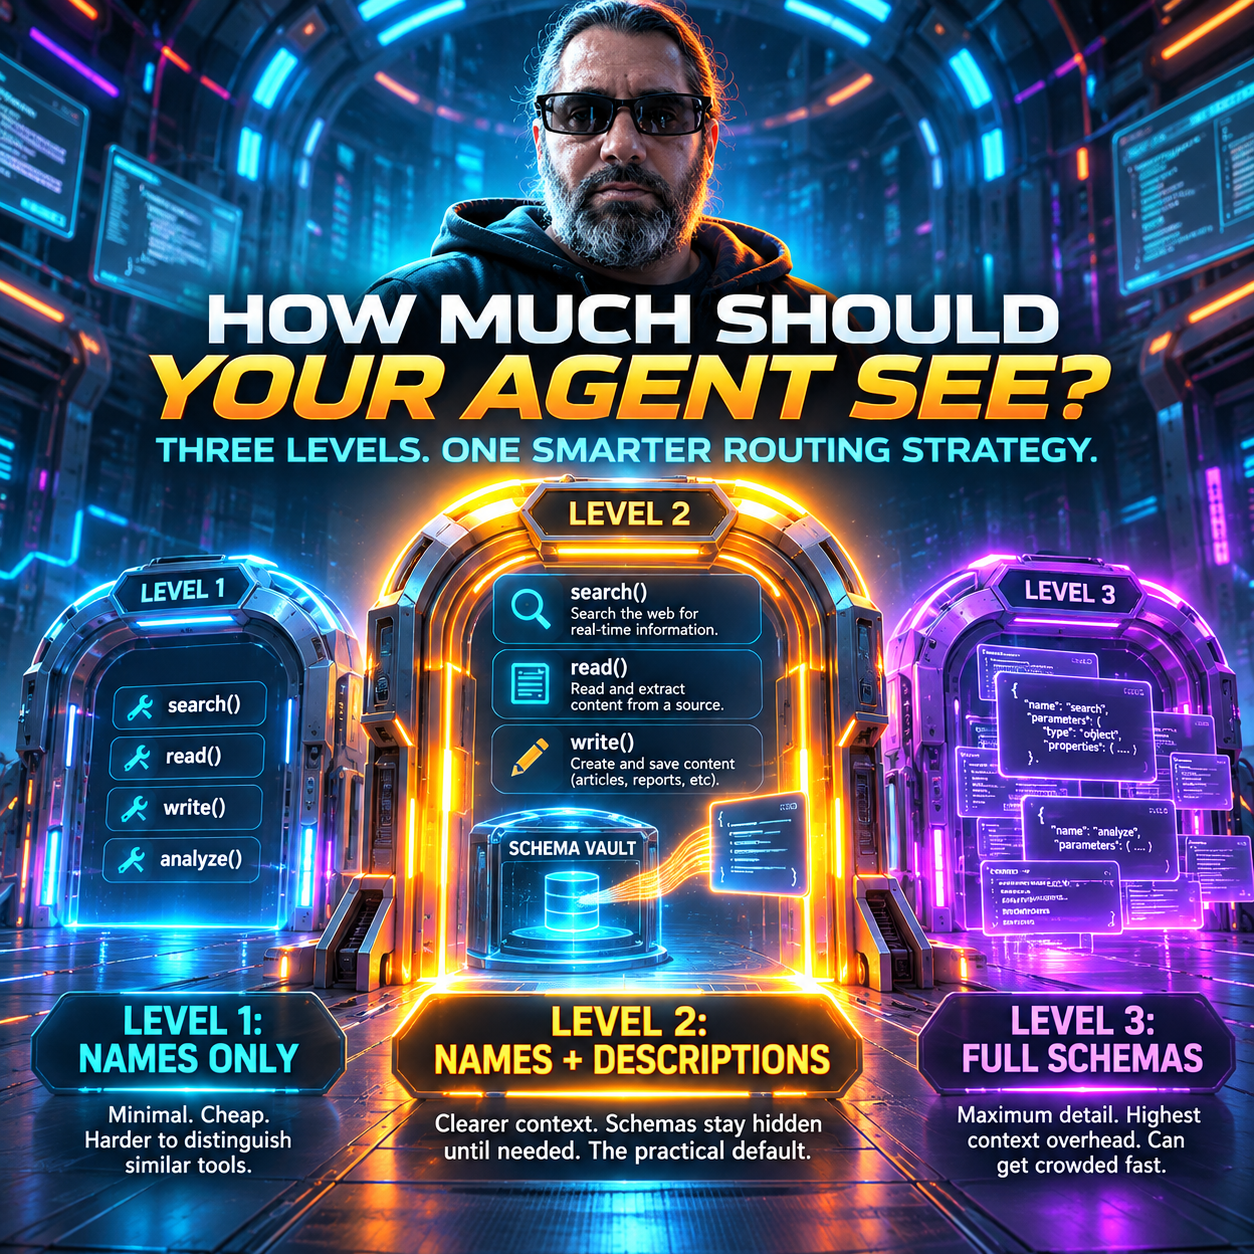
Level one is names only. It is the cheapest option, and it is the worst for subtle tools. If two tools both sound plausible from their name, name-only exposure makes the collision a coin flip. Use it only when names are unambiguous verbs and your catalog is small.
Level two is names plus descriptions. This is the tier Google built and the default you should run. It costs roughly a third of full schema injection, it preserves enough semantic signal for the model to route, and it pairs with the search tool as a fallback for the cases where a description is not enough. In practice this level is where most catalogs should live.
Level three is full schema injection. Maximum selection accuracy per tool, maximum cost, and at scale it recreates the exact problem you were trying to solve, because a large enough catalog of full schemas degrades selection accuracy on its own. It is the right choice for a twelve-tool agent and the wrong one for a two-hundred-tool platform.
Measure it yourself, and measure the thing that actually matters: selection accuracy on a fixed eval set of realistic requests, run at each level, with latency and token counts recorded beside it. Google published no accuracy table, no token savings percentage, and no benchmark in that announcement. What it published was a mechanism, a threshold in the documentation, and a ratio you have to compute. Anyone quoting a savings number for deferral in general is quoting their catalog, not yours.
The practical configuration most teams land on is a hybrid, and it is how you make a large catalog behave like a small one: leave your ten or twenty most-used tools undeferred, which Google explicitly recommends, and defer the long tail. Your hot path pays nothing extra and your cold path pays only when touched.
There is a second data point from this week that says the same thing from the other direction. Meta FAIR's Self-Improving Memory had a model write its own memory prompts, then distill those prompts into weights through a rank 64 LoRA adapter. The self-written prompts averaged 56.0 across three tasks against 44.6 for the best human-written harness. The codebase task hit 64.3, and that specific 20.6 point delta is the codebase gain over the best hand-written harness, not a three-task average. The base model, Kimi-K2.6, was the same on both sides of that comparison. Nobody shipped new weights to get there. Harness design is where the remaining gains are, and schema deferral is one lever on that same machine.
THE FAILURE MODES NOBODY MENTIONS
Deferral introduces its own failure modes, and they are quiet.
The first is that tool_search becomes the tool the model always picks. It is the one tool that can produce any other tool, so a badly tuned model will route everything through search, including calls it could have made directly. Cap the number of searches per turn, log every search, and alert when one conversation triggers more than a handful. A search loop is a signal, not a quirk.
The second is that description quality becomes load-bearing in a way it was not before. When the model sees a full schema, a mediocre description can be rescued by a well-typed parameter list. When it sees only a name and a description, the description is the entire routing table. This is why the 66 percent accuracy result matters so much in a deferral world: it was always the weakest link, and now it is the only link.
The third is collision. Deferred tools with near-identical descriptions get confused, and the search results make the confusion worse by surfacing both at once. If you have get_user and fetch_user, or search_docs and find_documentation, merge them or rename them. Two tools that mean the same thing are one tool with a routing bug.
There is a fourth, and it is the one that bites people during rollout. Deferral hides a schema from the prompt. It does not obviously remove that schema from the request, because the tool is still declared with defer_loading set on it. Google's docs describe a second pipeline that reads declared tools: when you set tool_choice to any, which forces the model to always call a function, or when you define complex parameter schemas, the API compiles your function declarations into a state machine that constrains token generation. That state machine enforces limits on total states, branching paths, and nesting depth across all declared tools, and exceeding them returns a 400 INVALID_ARGUMENT. That much is documented behavior, not my inference.
Where the documentation stops is where my hypothesis starts. Google never says whether a deferred tool counts toward that compiler budget, and the tool is still declared in the request with defer_loading set on it, so my engineering read is that the budget is unchanged by deferral. Test that on one request before you migrate. If your catalog already fails the complexity check, turning deferral on probably will not rescue it, because the compiler sees declarations, not prompt positions.
WHAT TO DO TODAY
- Audit the catalog: serialize every full schema, sum the characters, divide by four, and write the number down. Most teams find it is larger than their system prompt.
- Count what the same catalog costs at names plus descriptions, and compare the two numbers against your actual per-million input price and your caching rate, not against a vendor headline.
- Turn on deferral for your ten least-used tools first, and measure selection accuracy before and after on a fixed eval set. One week, one number, no opinions.
- Rewrite the three vaguest tool descriptions in your catalog, because deferral makes them the routing table.
- Log tool_search calls for a week and look for two patterns: loops, where the same tool name gets searched repeatedly, and dead retrievals, where a search returns nothing and the model retries with different words.
- Set an alerting budget on deferral rate. If searches exceed your threshold as a share of total calls, your catalog is too big or your descriptions are bad. That is a catalog problem, not a model problem, and it is yours to fix.
THE UNCOMFORTABLE QUESTION
If your agent picks the wrong tool today, is that a model problem, or did you hand it a 400-page menu and blame its eyesight?
Get More Articles Like This
Getting your AI agent setup right is just the start. I'm documenting every mistake, fix, and lesson learned as I build PhantomByte.
Subscribe to receive updates when we publish new content. No spam, just real lessons from the trenches.
Build Real AI Infrastructure
PhantomByte teaches you to build real AI infrastructure yourself: local AI stacks, autonomous agents, multi-agent orchestration, web scraping, and custom tools. Step-by-step PDF tutorials you download, follow, and deploy. No subscriptions. No fluff. Just skills that ship.