Researchers froze the prompt and the evidence set at four statements. Then they swapped one unrelated fact for an obsolete version of the fact the question was about, and Qwen2.5's accuracy fell from 100 percent to 44.6 percent.
The retrieval worked in every trial. A gold-assisted audit confirmed the newest statement was in the evidence set each time. The model read the current fact and answered from the dead one anyway.
Qwen3-14B, the bigger model, fell to 87.8 percent on the same swap. Scale did not make it immune. It made it slightly less exposed.
Now the part that should end the roadmap most teams are on. Growing the retrieved evidence budget from 64 tokens to 512 dropped BM25 accuracy from 45 percent to 32 percent on the same task. Eight times the context returned less truth. That is thirteen points gone, nearly 30 percent of the accuracy, and that arithmetic is mine, not the authors'.
Your RAG stack does not have a retrieval problem. It has an expiry problem, and almost nothing in production has a date field for it.
THE EXPERIMENT THAT SHOULD CHANGE YOUR MEMORY DESIGN
The paper is "When Retrieval Is Not Enough: Obsolete Facts in Agent Memory," arXiv 2610.36308, accepted at the NeurIPS 2026 PALM workshop and posted Monday. Seven authors, led by Oleeviya Babu Poikarayil. The task is single-hop FactConsolidation in MemoryAgentBench, on Qwen2.5-7B-Instruct over a 6K-token history with a plain BM25 retriever.
Stale means one thing here: an older version of a fact still sitting in the corpus next to the current one. Not a wrong fact. Not a missing fact. A fact that was true, got revised, and never got marked as revised.
The four-statement experiment isolates that variable: same prompt, same evidence size, same question, one swap. It tests one thing, whether the model prefers the newer version when both are in front of it. All 50 harmful paired flips in that setup were classified as stale. The damage is specific. An obsolete statement hurts more than an unrelated fact of identical size, so the model is not distracted by noise. It is reading the conflict and resolving it wrong.
This is not a small-context artifact. The authors replicated on a 32K history and found the same ordering: BM25 at 64 tokens scored 69 percent, at 512 tokens 58 percent. Same retriever, same model, more evidence, worse answers.
WHY BIGGER CONTEXT MAKES IT WORSE, NOT BETTER
Two years of RAG roadmaps assumed accuracy scales with how much evidence you stuff into the window. This paper measures the opposite.
Every extra retrieved token is another chance to pull in a superseded statement, because a vector index or a BM25 index has no concept of which of two contradictory passages is current. Both embed fine. Both match the query. The ranking function will happily order the old one first when its surface form matches the question more closely, which happens constantly when a product gets renamed and the old name is still in the question.
Then you hand the model a set holding the current fact and the dead one, and nothing in its weights says newer wins or tells it the corpus has a timeline. So it picks whichever reads more fluently, or appears later, or agrees with what it already believed. Those are three different tie-breaks, and none of them is a version comparison.
Keep the two stages apart, because one number hides both. Retrieval ranking decides what reaches the window, on term overlap alone, so a bigger budget admits more superseded statements. Generation decides what happens once both versions are in front of the model. The 45 to 32 percent drop is the two stages compounding, not a perplexity measurement and not a verdict on lexical scoring, since the ranker put the newest statement in the pool every time.
Your planned fix, retrieve more and let the model sort it out, is the failure mode the paper measured. You are not adding evidence. You are adding candidates for the wrong answer.
THE DECISION-RULE TRAP: WHY "ALWAYS TRUST THE CONTEXT" IS MATHEMATICALLY WRONG
The first paper showed the conflict your own retrieval manufactured. The second starts where that stops: what the model should do when the dispute is already in the window. It kills the obvious patch. "Don't Pick a Winner: Knowledge Conflicts Need a Prior, Not a Rule," arXiv 2610.36169, by Minh Pham Van and Cong Tran, examines the moment a retrieval-augmented model holds two sources that disagree, the retrieved context and its own weights.
Every team patches that moment with a rule fixed at design time: follow the context, amplify it in proportion to how far it moves the model, or trust the model's memory. Pick one and ship it.
The authors show decision-theoretically why all three lose. The score of any fixed rule is linear in the share of reliable contexts. The best attainable score is convex. A straight line can never sit above a convex curve everywhere, so every fixed rule is beaten somewhere it is not exactly optimal. They also show that the symmetric divergence between the two sources, which adaptive decoding methods use as their signal, carries no information about which source is right. A confident disagreement and a confident agreement look identical to that feature.
The replacement is not a better rule. It is a prior. Keep evidence about each source separately, keep a running estimate of how often your context is actually right, and apply that estimate as a shift when the sources conflict.
On the GRACE benchmark, which intervenes on the knowledge-graph context of a fixed question so that what the model knows, what the context says, and what is true are measured apart, setting that prior to the true share of right contexts beat the best baseline at every mixture, by up to 26 points. The overall scores were 45.3 and 35.0 for Qwen3.5-35B-A3B and Llama-3.1-8B, against 29.4 and 27.5 for the strongest baseline. On the preregistered ClashEval set it beat same-backbone CK-PLUG and TCR by 12 and 26 points.
One honest limit: where the model lacks the knowledge, the gains vanish, as the theory predicts.
THE SUPERSESSION FILTER: THE WRITE RULE YOUR MEMORY LAYER IS MISSING
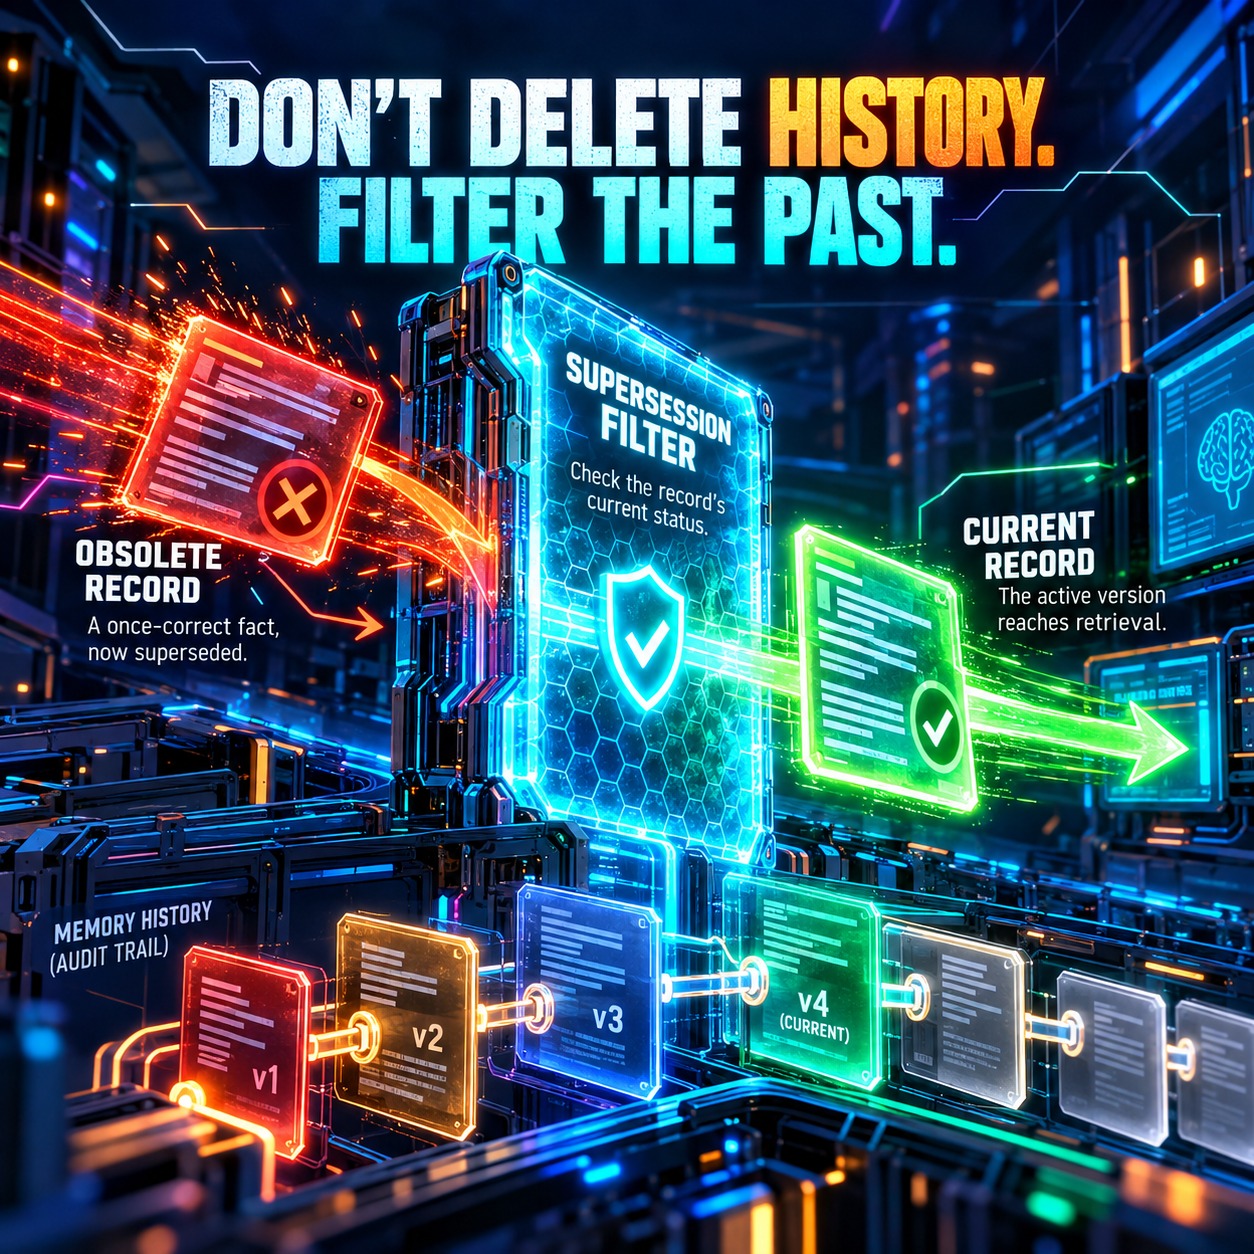
Here is the framework to take to your schema, and it is where the two papers meet. I call it the Supersession Filter: three fields plus one check. It is structural preprocessing: it keeps a superseded record out of the candidate pool, which stops the preventable conflict at the cost of one filter and no model change. The prior is the runtime answer for the conflicts left over, where both sources are current and still disagree. Filter first, because a conflict you prevent is one the model never has to adjudicate, and the ones that remain are the only ones where its judgment should count.
Every memory write carries three fields. Supersedes names the fact this one replaces, or null. Valid_from records when it became true. Superseded_by stays null until something replaces it, then holds the id of the replacement.
The check runs at retrieval time: drop any statement whose superseded_by is set. Not at write time, and not as a delete. The old versions stay in the store, because you will need them for audit, for rollback, and for answering the question "what did we believe in March." This is a filter, not a tombstone.
Four implementation rules, in order of how much pain they save.
- First, hash the subject entity, not the sentence. You want to chain every statement about "acme-primary-region" together, and you do not want a reworded sentence to look like a new subject.
- Second, writes to the same subject hash create a chain: the new record sets the old record's superseded_by to its own id, and its supersedes to the old id. Both directions, because you will query from either end.
- Third, retrieval returns chain heads only. One line of filtering in front of your reranker, and the reranker never sees the dead version.
- Fourth, log every drop. A dropped supersession you did not know about is a business-logic bug, not a retrieval win, and the only way you find it is the log.
There is a symbolic precedent, and it is back in fashion for this reason. AWF's ZPM is a Zig and Prolog reasoning server exposing 22 MCP tools for facts, rules, queries, and proofs. It runs an embedded Trealla Prolog engine with truth maintenance and assumption tracking, plus a write-ahead journal and point-in-time snapshots. That is the old symbolic answer to dependency-tracked belief revision, packaged as agent tools, and the industry is now rebuilding it badly in vector stores.
KEEP THE DERIVATION RUNNING: WHY STORE-ONCE ALWAYS ROTS
If the lesson were only about facts, you could stop. It is not. "Skill Dreaming: Evolving Repository Skills through Pull Request Streams," arXiv 2610.36188, by Xinyuan Song and five coauthors, shows the same decay in a different artifact. Repository skills built once against a snapshot of a codebase go stale silently as structures and conventions move. Their fix is to re-derive skills continuously from the PR stream, which records what the repository actually decided, and feed the result back into future PRs. PRs train skills, skills produce better PRs.
The rule generalizes past code. Any statement extracted from a source that changes needs a re-derivation loop, not a storage policy. A snapshot of a moving system is a stale fact with a confident timestamp on it, and your memory layer is not a database. It is a cache with opinions about freshness.
PhantomByte has covered the storage side of this in "Agent Memory Is a Dataset, Not a Service" and the speed side in "Your Agent's Memory Is Too Slow to Think." Neither touched contradiction or versioning: what happens when two records are both correctly stored and only one is still true.
WHAT TO DO TODAY
- Grep your memory store for the same entity stored twice, and count the pairs. That count is your exposure.
- Add superseded_by to your memory schema. One field, then backfill the obvious chains.
- Move the staleness check to retrieval time, so your reranker never sees a dead record.
- Pick your most-used context source and log whether the context was right or stale on every query. That log is your prior, and the second paper says the prior is the whole game.
- Rerun your eval set with the filter on and compare. The delta is your stale-fact exposure, in points.
THE UNCOMFORTABLE QUESTION
You already know some of your agent's answers come back from last year's version of the truth. You have never measured how many, because measuring it means admitting your context pipeline has been quietly poisoning the model while you upgraded everything around it. How many points of accuracy are you willing to lose this quarter rather than add one date field?
Get More Articles Like This
Getting your AI agent setup right is just the start. I'm documenting every mistake, fix, and lesson learned as I build PhantomByte.
Subscribe to receive updates when we publish new content. No spam, just real lessons from the trenches.
Build Real AI Infrastructure
PhantomByte teaches you to build real AI infrastructure yourself: local AI stacks, autonomous agents, multi-agent orchestration, web scraping, and custom tools. Step-by-step PDF tutorials you download, follow, and deploy. No subscriptions. No fluff. Just skills that ship.