A customer replays the exact same prompt and gets a different answer. Same model, same tokens, same temperature at zero. They swear nothing changed on their side, and they are right. What changed is who else was in the batch at that moment.
A paper posted to arXiv on November 4 called BlockLock finally quantifies that bug class and ships a fix with numbers attached. Pin one request's execution geometry and you can cut latency 53.5 to 55.0 percent and raise throughput 115.2 to 122.2 percent against the standard batch-invariant approach, without a custom kernel and without slowing anyone else in the room.
We covered the training half of this contract in "Bitwise Determinism in NVIDIA Megatron Core: The 2% Cost of LLM Reproducibility" back in October. This is the half nobody had solved: how to make one request reproducible while everyone else keeps sharing the batch.
THE BUG NOBODY OWNS
Batching means multiple requests share one GPU pass. That is why serving is cheap. It is also why your output can move.
Floating point addition is not associative. Add the same numbers in a different order and you land on a slightly different value. A shared kernel splits a matrix multiply into chunks based on the shape of the tensors it was handed, and that shape depends on the longest prompt in the batch, the padding around yours, and how many rows the scheduler packed in. Change the companions and you change the reduction order. Change the reduction order and the logits shift in the last few bits, which is all it takes for a token in a near tie to flip, and once one flips the rest of the sequence follows.
Logits are the model's raw score for each next token. Top-20 logit agreement means the same twenty candidates with the same raw values at every step, and that is the bar this paper holds itself to.
So temperature zero does not protect you, and neither does greedy decoding or a fixed seed, because nothing about the sampling was random in the first place. This is a numerical path problem wearing a sampling problem's clothes, and it hides in the one part of the stack nobody instruments.
You have seen the symptoms if you have run a harness twice. Benchmarks that score a point or two apart on identical code. Judges that flip a verdict overnight. Regression tests that pass on Monday and fail on Tuesday with no commit in between, the kind of failure that gets blamed on the data pipeline because the model feels like the stable part.
We wrote about that variance in "Your Evaluation Harness Moves Your Benchmarks 4.3 Times More Than Your Training Recipe." This is the mechanism underneath it, and the paper puts a number on the size of the hole. On its single-GPU subset, standard padded batching reproduces the target sequence only 52.59 percent of the time once the companions change, and matches Top-20 logits only 35.93 percent of the time. Across two A6000s with one Gemma-3-4B split in half, agreement fell from 100 percent at batch size one to 72.4, 43.6 and 21.8 percent at batch sizes two, four and eight. The paper also notes the default backend path can vary even at batch size one, which should bother anyone who assumes isolation is the safe default.
Half the time, your deterministic evaluation was never comparing the same computation to itself.
THE TWO OLD FIXES AND WHAT THEY COST
The paper frames the existing options as two bad trades, and it is right.
Batch-invariant kernels constrain every operator to one fixed arithmetic order so the batch size stops mattering. Everyone pays. In the paper's own table the penalty runs 117.5 to 149.5 percent higher latency than standard vLLM across eight datasets, more than double the wall clock for every request on the node, and someone has to maintain those kernels for each hardware target.
The CoRun-style alternative isolates prefill, running each request alone at batch size one, then decodes inside a fixed-shape batch. You give up shared prefill compute entirely, and decode pads to a fixed 256-slot envelope whether or not you have 256 requests, so low occupancy burns masked slots.
Determinism has always been priced as a fleet-wide tax. BlockLock attacks that assumption, one most platform teams inherited without costing it out.
BLOCKLOCK: PROTECT THE REQUEST, NOT THE FLEET
The design move is to stop fixing the batch and start fixing the geometry that one request sees. Shared batched prefill stays. The protected request gets a shape that does not move when its companions do.
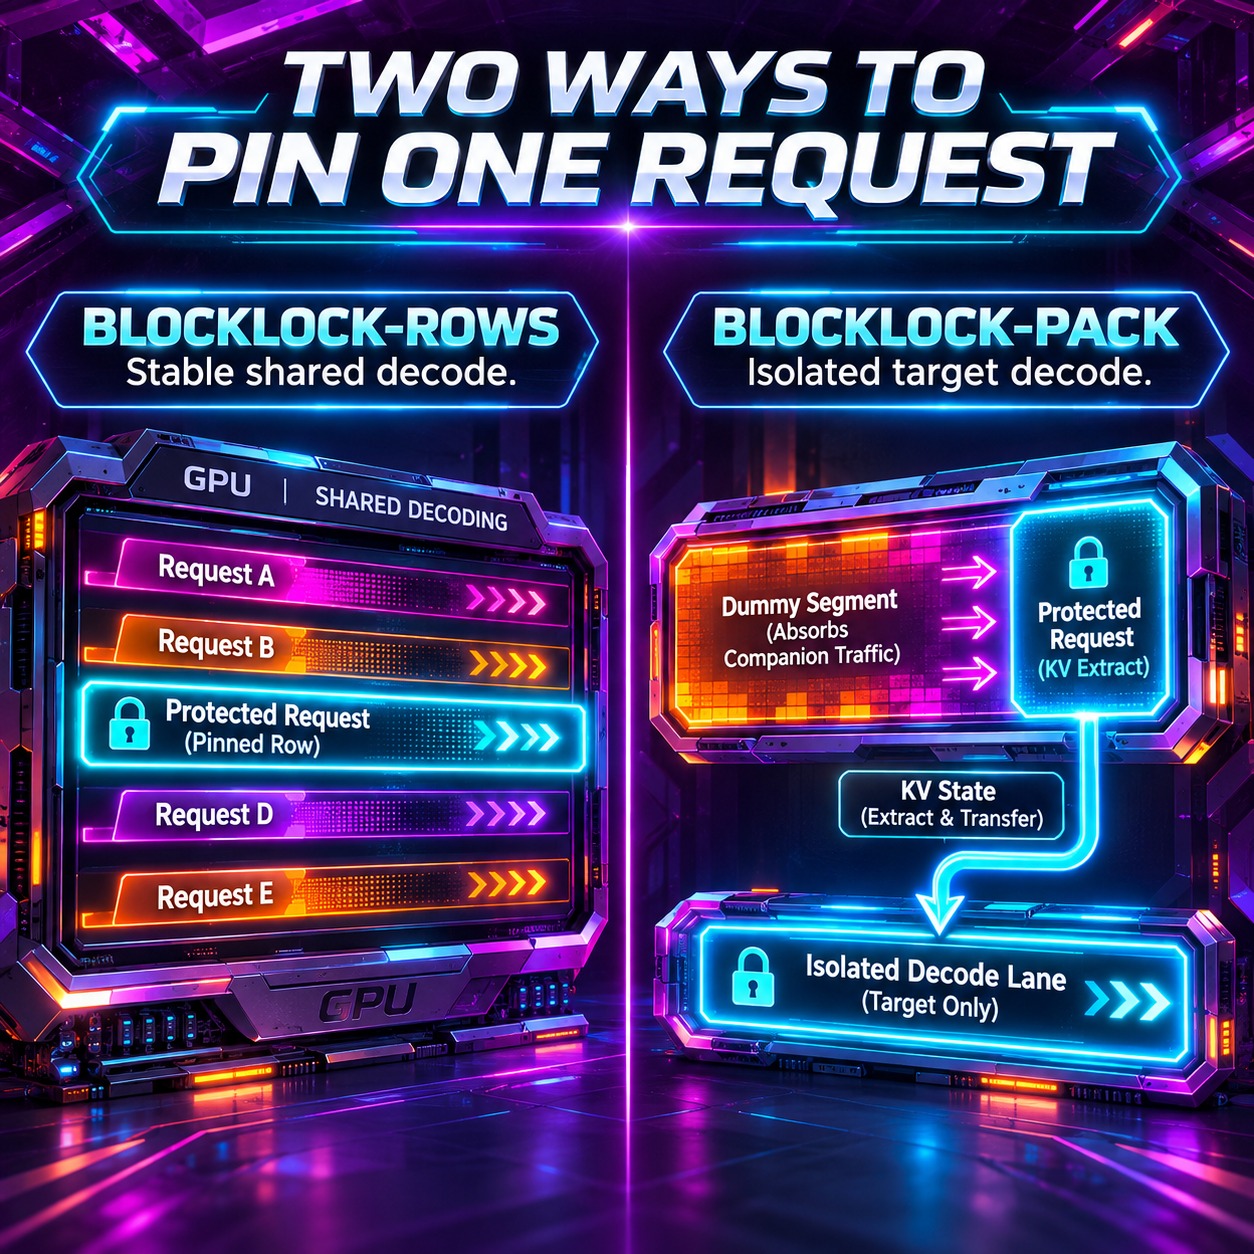
BlockLock-Rows cuts prompts into fixed-width rows of a length class chosen in advance, so the protected request always occupies a stable row in a tensor of known width. Batched decode survives for every request in the group, which makes this the throughput option rather than a quarantine.
BlockLock-Pack packs everything into one block, anchors the protected request at the end, and fills the remaining space with an isolated dummy segment that absorbs whatever the companions did. After prefill it extracts that request's KV state and decodes the target alone. That is the isolation option: the audited answer never shares a decode step with anyone.
The bar for both is bit-identical output: same token IDs, same raw logits, at every step, for any set of companions. The paper validates it under three named conditions, canonical geometry, repeat-stable arithmetic and faithful cache handoff, and reports 100 percent sequence and Top-20 agreement across eight datasets, five dense models and three GPUs, with four targets per dataset and ten repetitions each.
Here is the sentence that matters most, the one a vendor deck would bury. The guarantee holds per deployment configuration. Change the GPU architecture or the tensor-parallel degree and the reduction trees underneath change with it, so the contract has to be re-established and the operators re-checked. This is a contract on a deployment, not a property of a model, and that distinction is mine. Anyone who reads reproducible inference as a model-level claim will run the same test on a different card and be surprised.
THE NUMBERS TABLE
The test fleet is five dense models, Qwen3-8B, Qwen3-14B, Llama-3.1-8B-Instruct, Gemma-3-4B-IT and Gemma-3-12B-IT, on an A6000, an A100 and an H100, scored on tinyBenchmarks and BFCL.
At equal delivered work against vLLM with batch-invariant kernels, BlockLock-Rows cut total execution time by 55.0 percent on Qwen3-8B and 53.5 percent on Qwen3-14B, and lifted output throughput by 122.2 and 115.2 percent. Those pairs are one result: it runs 2.15 to 2.22 times faster than the deterministic baseline it replaces.
Now the number that decides adoption, and it is not the headline. Against ordinary non-deterministic vLLM, the fast path you already run, Rows costs 5.4 to 6.9 percent geometric-mean latency across the eight datasets. In native PyTorch it costs 0.5 to 0.8 percent over padded batching. That is the whole trade: a single-digit tax to buy bitwise output on the requests you care about, instead of a hundred percent tax on everyone.
Pack is a different workload, so do not compare its wall clock to the full-batch numbers; it decodes the target only. At long generations that is where isolation pays. In the paper's fixed-target table at width 1024 with 2048 output tokens, Pack finishes in 36.7 seconds where padded batching takes 73.0. When the audited answer is the only output anyone needs, skipping companion decode is worth more than the padding costs.
And the other tenants never notice. The constraint attaches to the protected request, not every request on the node, and there is no custom kernel to maintain per GPU generation.
THE DECISION TABLE: WHO NEEDS BITWISE STABILITY
Pin the request when a human or a regulator will later ask why it said that.
That means evaluation and benchmark scoring, LLM-as-judge pipelines where a flipped verdict moves a leaderboard, regulated outputs, cache validation where a hit has to return exactly what was stored, and anything feeding an audit trail. If two runs of the same input can end up in a document a compliance team signs, that request needs a pinned numerical path.
Then there is the agent. An agentic control flow is a chain where each step eats the previous step's output, so a flipped token in a tool-selection router does not stay local. It changes the tool, which changes what comes back, which changes the next decision. By step three the execution graph is a different shape.
If an agent decides whether to call an API off a razor-thin logit margin, deterministic tool-use regression testing is the only way to know you graded the same code path twice. That means BlockLock-Rows on the runs you compare, or your agent regression suite is measuring batch noise and calling it behavior.
Do not pin live chat with sampling on, draft generation, or internal search where top-k variance is tolerable. Nobody will replay those, and the padding is real money at scale.
The decision rule is one line: if no one will ever replay it, do not pay to pin it, and if someone will, pay the six percent and stop pretending the alternative is free.
Two limits belong in the same breath. The paper covers dense models only, and mixture-of-experts routing, where capacity-factor dropping creates its own interference, is explicitly left to future work. Padding waste also rises when companion lengths vary wildly inside one coarse length class, so a badly sized class width eats the savings, and chunked prefill and prefix caching are not integrated.
WHAT TO DO TODAY
- Grep your serving config for batch-invariant or deterministic flags and work out what you actually pay for them. Most teams turned one on during an incident and never measured it again.
- List the request classes that could ever land in an audit. Evals, judges, compliance outputs, cache validation. That list is your protected set, and it is usually a small fraction of traffic.
- Check whether your eval harness can run the same prompt in the same batch mix twice. If it cannot, your regression numbers are noise, and the harness piece above shows how much.
- Read arXiv 2611.06977 before your next serving-stack review. The two modes map to two contracts, and you may need both: Rows when the group's output matters, Pack when only the audited target's does.
THE UNCOMFORTABLE QUESTION
If your platform cannot tell you whether an answer would come out the same tomorrow, what exactly did your compliance team sign?
That question gets worse with every step you add. One endpoint flipping a token is an annoyance. A ten-step agent with a batch-dependent router is an audit finding, because the trace you saved and the trace you would get today are different programs.
You do not have reproducible AI. You have reproducible luck.
Get More Articles Like This
Getting your AI agent setup right is just the start. I'm documenting every mistake, fix, and lesson learned as I build PhantomByte.
Subscribe to receive updates when we publish new content. No spam, just real lessons from the trenches.
Build Real AI Infrastructure
PhantomByte teaches you to build real AI infrastructure yourself: local AI stacks, autonomous agents, multi-agent orchestration, web scraping, and custom tools. Step-by-step PDF tutorials you download, follow, and deploy. No subscriptions. No fluff. Just skills that ship.