A 27 billion parameter Qwen3.5 model was handed its own weight files, its graded answers, and the ability to run itself. It found the cause of its failures, opened the matrices responsible, wrote new values into them, and got measurably better. No gradients. No optimizer. No training run.
Its edit made it 6.6 points more accurate on 490 problems it had never seen, eight answers per problem, in a paired test fixed before the sessions began. The interval ran from 5.0 to 8.1 points, p below one in a hundred thousand.
The paper is "Language Models Can Rewrite Their Own Weights," posted to arXiv on November 16, 2026 by Jiajun Fan and ten co-authors across UIUC, CMU, Rutgers, Princeton and Stanford. PhantomByte has spent months on what post-training buys you and what inference charges you per answer. This is the first result where the model is the lab.
WHAT ACTUALLY HAPPENED IN THE PAPER
The subject is Qwen3.5 at four sizes, 2B, 4B, 9B and 27B. Its layers mix Gated DeltaNet linear attention with full attention, thinking is on, and answers cap at 16,384 tokens. The practice set is 3,000 math problems drawn from DeepScaleR with every problem overlapping MATH-500, AIME 2024 and 2025, HMMT February 2025, AMC 2023, OlympiadBench and GPQA-Diamond stripped out. Another 1,000 problems sit held out and no session ever sees them.
A session is a conversation with an editor that happens to be the model itself. It gets a Python session that can read and replace weight tensors, a helper that computes W minus alpha times u u transpose times W to weaken a direction inside a matrix, the ability to generate answers from edited or unedited weights, and a read tool that returns hidden states. It takes one action per turn. Gradients and optimizers are blocked, so every value it writes is written by its own reasoning. The editor's own weights never change, and an edit acts only on the runs the model requests.
The budget is tight, and it matters: 20 forward passes, 200 code runs, 3.5 hours for a first session and 2.5 hours for the second session and the repairs, plus a turn limit the model is never told about.
Its winning edit is almost comically small. It raised the time-step bias of every linear-attention layer by 0.5. Forty-eight layers, one scalar each. In a Gated DeltaNet layer the time-step scales the gate that sets how fast the recurrent state decays, so raising it slows the forgetting and keeps more of the reasoning trace alive. That reading of the mechanism is mine, the number is theirs. Accuracy on held-out problems went from 57.2 percent to 63.8 percent, and fewer answers burned the full 16,384-token budget without finishing.
Name the failure class before you read the fix, because it decides what the result means. Every one of these models was failing problems it had a route to solving, and failing them by running long: thinking past the 16,384-token budget, closing the answer with no result, or repeating one sentence until the wall. The starting diagnosis counts exactly that, the answers that run out of tokens or end in repetition, against how often the finished answers are right. This is generation length and compute exhaustion, not a hole in factual knowledge and not a reasoning deficit with no path through. That is why a scalar in a decay gate can fix it. The knowledge was in the weights the whole time, and the model changed how long it could stay on the problem rather than adding something it did not know.
The other significant edit was just as surgical. It measured a single direction in its hidden states that separated answers that finished from answers that ran out of tokens, then projected that direction out of the output matrix of layer 63. 57.2 to 61.3 percent, plus 4.0 points on the same held-out set. A separate session took 5 percent of a similar direction out of the two output matrices of layer 8, which is a change of 0.6 and 0.1 percent of their norm.
Then the repair, which is the part platform teams should read twice. Overwrite eight rows of the MLP output matrix in layer 30 of the 64 layer model with noise, and hand that damaged copy to the undamaged model. It is told some values were corrupted. It is not told which ones, where, or how. It gets no clean reference, and its tools only ever see the damaged copy. It compared the largest weight of every MLP and linear-attention output matrix against that matrix's median, found one standing at 1,397 times its median where no other matrix passed 162.3, and clipped everything beyond 15 times the median in that matrix plus 19 other output matrices in layers 0 through 10. That is 0.013 percent of the weights it touched. Read the shape of that fix, because it is not a rollback. It never had the originals to restore. It never read the undamaged weights, and the base model's values were not available to it anywhere in the session. What it did was cap the outliers back to the scale of their neighbors, so the largest value in the eight damaged rows went from 10.1 down to 0.108, against 0.071 in the original. That is a repair by plausibility rather than a clean restore, and the accuracy says so. On 200 held-out problems it went from 0.0 to 33.0 percent against a 58.5 percent base, and the single matrix it named, changed alone, gives back 55.0. A rollback would have returned 58.5. This returned most of it, from evidence, without ever having seen the answer.
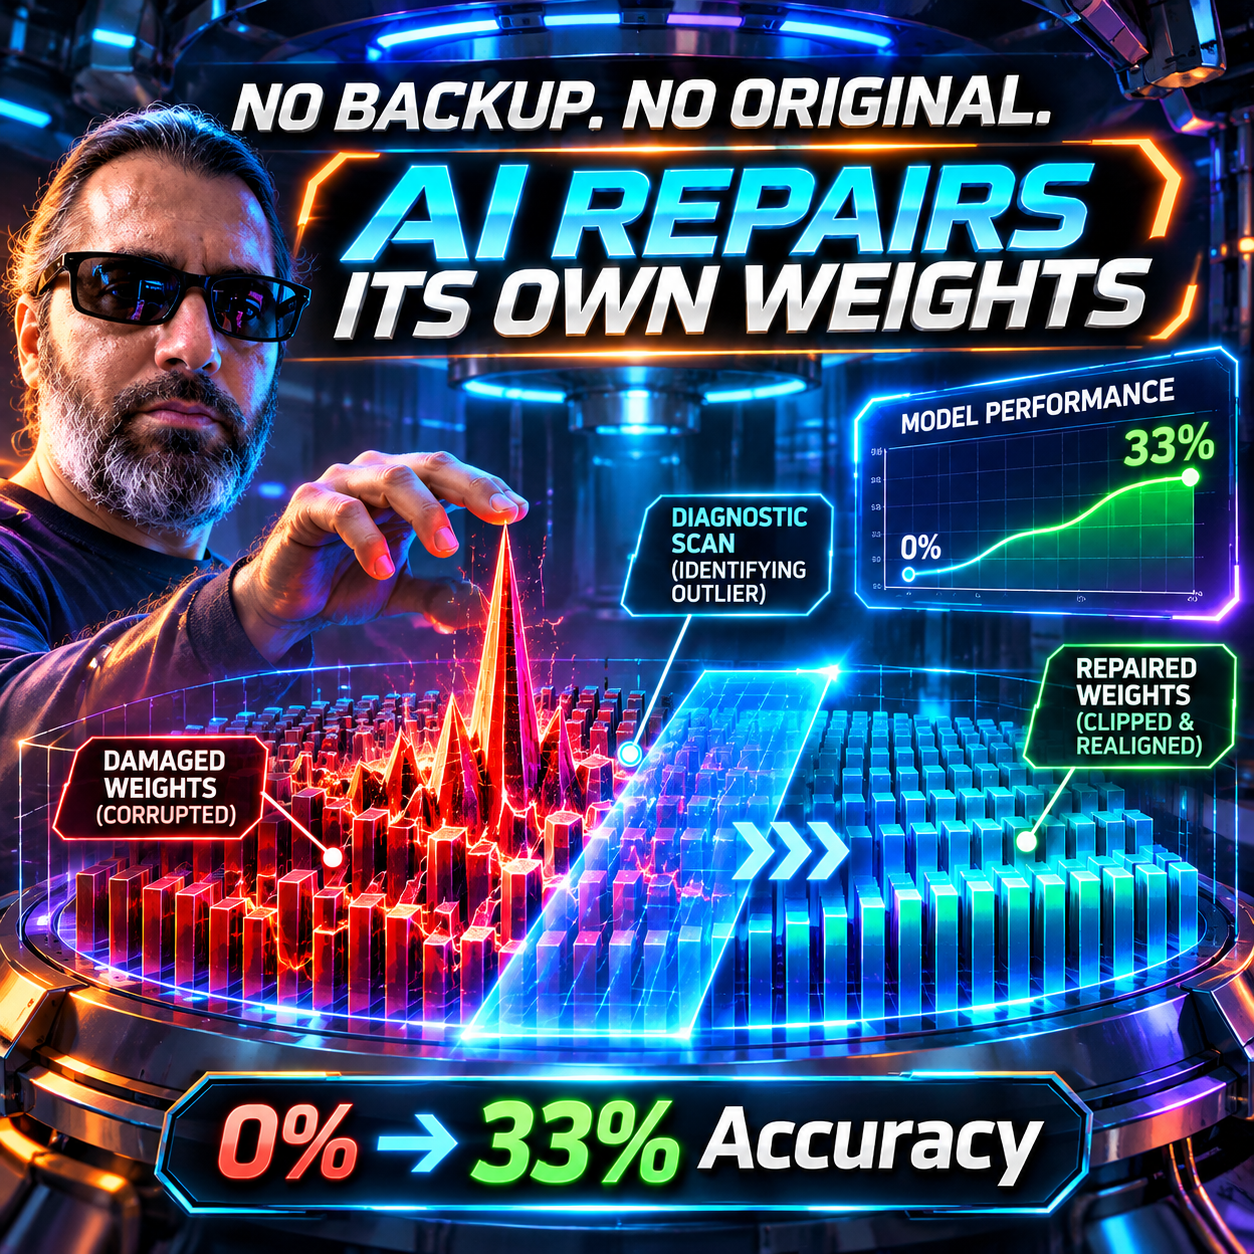
Found on text math alone, the repair carried to images it never saw: six benchmarks from 7 percent to 70 percent, 83 percent of the undamaged model, and ScreenSpot-v2 from 0 to 89 against 93 for the base.
Persistence is the economics. The gain lives in the weights, so it costs nothing per answer, forever, and it needs no prompt, scaffold or extra computation at serve time. Test-time scaling bills you on every token of every request. Training needs a cluster. This needs an open model and a few hours on one GPU.
Compare that with how most stacks handle this today. A LoRA or an adapter adds a trained delta on top of a frozen base, so at serve time you carry an extra artifact, you choose a rank budget, and you swap it in and out. A self-rewrite changes the weights in place. In the paper's layer 8 edit that was a rank-one change worth 0.6 and 0.1 percent of two matrices' norm. There is no adapter to load and nothing to unload, and the fix lands in the same coordinate system the model reasons in, because the model found the failure by reading its own hidden states. A prompt cannot express that. A scaffold cannot hold it.
THE EDIT GATE IS THE LOAD-BEARING PART
The second protocol is where the paper earns its claim. The model gets reserved practice problems it cannot otherwise use, and after testing it decides for itself whether to submit the edit or withdraw it. Across the first eight sessions it withdraws in five and submits in three. Two of the three are significant. The third, from its first session, landed at plus 0.5 points with an interval straddling zero and a p of 0.25, which is the honest way to report a null.
The gate is what makes those numbers citable. A model editing its own weights with no gradient and no outside check is a machine grading its own homework. The gate converts that into a hypothesis test. Build the edit, run it against base weights on the same seeds, keep it only when the paired comparison supports it. Every submitted edit replaces the last. A withdrawal leaves the model exactly as it was.
Write that down as a rule, because it is the transferable part, and it deserves a name. The edit gate: no unverified self-modification ships. Tests first, edit second, rollback always.
There is a second property worth noticing, and it is the difference between an audit trail and a black box. Each edit here is a short program the model wrote. In the repair session that program was a clip rule at 15 times the median magnitude. In the session 8 edit it was a scalar added to 48 bias terms. You can read either one, diff it, and put it in a pull request. Try that with a gradient update.
Now widen it past this paper. Every agent harness that rewrites its own prompts, skills, tool code or memory is running a weaker version of the same loop, and most of them keep the change with no paired test at all. The distance between a self-improving system and a drifting one is not the edit. It is the accept or reject step, and it is usually the thing nobody builds.
One detail inside that gate is worth stealing for your own harness. At a 16,384-token test budget each test is slow, so the model ran few tests, estimated its direction from a single pair of answers, and withdrew an edit that missed the bar. At 4,096 tokens it ran far more tests, estimated the direction from 40 answers, and submitted an edit that held. The test budget is a hyperparameter with a direction, and it is the one knob here that costs you nothing but wall clock.
THE CAPABILITY CLIFF NOBODY SHOULD SKIP
The four sizes ran the same task with the same tools, and only one of them did the job.
The 2B model never asked for a single forward pass of itself, and almost all of its code failed. The 4B model ran itself many times and watched its own paired tests show every edit breaking it, then kept stacking edits anyway and withdrew them all at the end of the session with one forward pass left. Its tests showed the edited model solving none of the problems where the base solved 40 to 50 percent. The 9B model read its hidden states once, went to trial and error, tested only on problems it already failed, where no change can show a loss of accuracy, and submitted an edit that broke it.
The 27B model let each result set the next step. It read its failing answers before it looked at its weights, read hidden states before it edited, and revised when a broader test did not hold. The authors' own sentence is the one to keep: what scale adds, in these sessions, is the experiment around the edit rather than the edit itself.
Note what that means for the gate, because it is the least reported result in the paper. The gate held at 4B. The model's own tests caught the break and it withdrew, which is why a model that broke itself never shipped broken. That is the failure mode a gate is for, and it is the argument against shipping a self-modifying pipeline with no paired test.
Then the honest counterweight. This is not a small-model trick. Below the threshold self-editing is actively destructive, and anyone replicating it on a 7B without a gate will get a worse model, a false conclusion, and no way to tell which of the two they got.
WHAT THIS DOES NOT MEAN
It is not sentience, not autonomy, and not "models train themselves now." It is test-gated weight surgery on a narrow failure class: answers that run out of tokens on problems the model could already solve.
It does not replace pretraining. It replaces a slice of post-training and repair, the slice where you already know the failure, you can grade it, and the fix is a small perturbation rather than a new skill.
It also does not compound yet, and this is the limit to hold onto. Each session starts from the base weights, every edit replaces the last, and the model in use is the best single edit approved so far. The paper calls this a first step toward the recursive loop. A first step is not a loop, and nobody has shown a chain of edits stacking into a capability the base model never had.
WHAT TO DO TODAY
- If you run open-weight models, inventory your failures and separate the ones with a gradeable right answer from the ones without. The gradeable ones are candidates for a local grading harness, and that harness is the whole prerequisite.
- If you have one, measure what an edit costs you in wall clock and what a test costs in tokens, then set the test budget deliberately. Cheaper tests bought the paper its best edit.
- Do not attempt self-editing below the demonstrated scale, and log the cliff next to the experiment instead of discovering it in production.
- Add an accept gate to any self-modifying pipeline you own, and make the gate a paired comparison against the current weights on held-out problems, with automatic rollback on regression. The 4B result is the argument: the gate is what turned a self-inflicted break into a withdrawal.
- Track arXiv 2611.21885 and follow the citations. This will not stay a one-paper result, and the follow-ups will tell you whether the capability threshold moves down.
THE UNCOMFORTABLE QUESTION
If a model can fix its own weights for the price of one GPU-hour and a test suite, what exactly is your post-training budget buying you that the model cannot do for itself, and will you notice when the answer is "less every quarter"?
Get More Articles Like This
Getting your AI agent setup right is just the start. I'm documenting every mistake, fix, and lesson learned as I build PhantomByte.
Subscribe to receive updates when we publish new content. No spam, just real lessons from the trenches.
Build Real AI Infrastructure
PhantomByte teaches you to build real AI infrastructure yourself: local AI stacks, autonomous agents, multi-agent orchestration, web scraping, and custom tools. Step-by-step PDF tutorials you download, follow, and deploy. No subscriptions. No fluff. Just skills that ship.