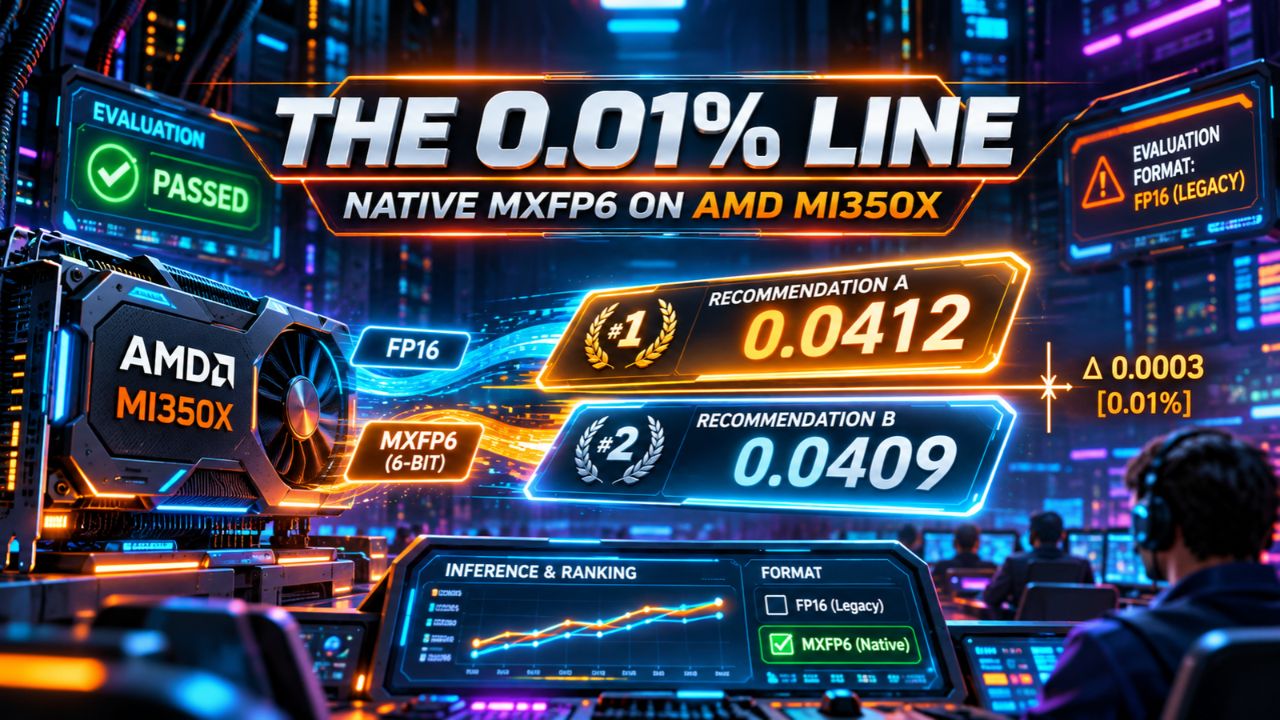
A recommendation model holds a 0.01% normalized entropy margin. Not one percent. One hundredth of one percent. That is the number a Meta and AMD team put in the abstract of a paper posted to arXiv on November 12, 2026, and it is the number your launch review is quietly holding whether or not anyone in the room can say it out loud.
Language models get to tolerate a full percent of accuracy loss after quantization. Production ranking and recommendation models do not. An LLM answers with tokens, and a small error rate spreads across a long answer. A ranker does not spread anything. It makes one prediction per item, sorts the list, and ships. When two ads score 0.0412 and 0.0409, a format change that flips their order changes what the user sees and what the advertiser pays.
Which is why the format discussion is not a tuning conversation. When the numeric format changes under you and the eval harness stays the same, the harness stops measuring the model. It starts measuring itself.
WHY RANKING MODELS LIVE AT 0.01% AND LLMS DO NOT
Start with the metric, because nobody defines it and everybody argues about it. Normalized entropy is the entropy of a model's predicted probabilities divided by the entropy of a model that predicts the base rate for every item. Lower is better. It moves when calibration moves and when the sharpness of the predictions moves, so it catches a model that has stopped separating good impressions from bad ones. In ads ranking it is the number the launch gate reads, and the gate in this paper is a relative one: the new model's NE may not rise by more than 0.01% against a production baseline that is usually measured at FP16 or FP32.
That asymmetry between a ranker and a language model is not a matter of taste. An LLM is graded on an average over millions of tokens, and an error rate of one percent still leaves a usable product. A ranker is graded on the ordering of items that sit inside a hundredth of a point of each other. The perturbation that matters is not average error. It is the sign flip on a pair.
MXFP6 is a microscaling format, and the definition does work later in this piece. Six-bit elements, in either an E3M2 layout with three exponent bits and two mantissa bits, or an E2M3 layout with two exponent bits and three mantissa bits. Values travel in blocks of 32 with one shared power-of-two scale per block, an 8-bit E8M0 exponent. Add the amortized scale storage and the real cost is 6.25 bits per value, not 6.
WHAT MI350X ACTUALLY SHIPPED
AMD's own spec page for the Instinct MI350X lists fourth-generation CDNA, 288 GB of HBM3E, 8 TB/s of memory bandwidth, and what AMD calls expanded MXFP6 and MXFP4 datatype support. The peak table is the interesting part. MXFP6 matrix throughput reads 9.2 PFLOPs, MXFP8 reads 4.6, and FP16 reads 2.3.
Read those three numbers together, because they carry the architectural argument. On this part MXFP6 peak is exactly double MXFP8 peak, exactly four times FP16 peak, and precisely equal to MXFP4 peak. The reading is mine, not AMD's: a 6-bit format costs nothing in throughput against a 4-bit one here, so the extra mantissa bit is free, and the only reason to ship 4-bit instead is that you need the memory, not the math.
Then there is the detail that makes the free-mantissa claim concrete. The paper walks through the two MXFP6 variants and lands on E2M3. Because the block scale is a power of two, scaling only shifts exponents and never changes how an element's mantissa rounds. Every value inside the normal range therefore quantizes to the same number it would take in MXFP8, which has the identical three mantissa bits. Only subnormal values diverge. So the format that runs at twice the rate of MXFP8 is, for the range that matters, carrying the same precision as MXFP8.
Native is the word doing the load bearing, and it needs to be defined precisely. Native means the matrix instruction consumes 6-bit operands and accumulates without a dequantization round trip to BF16 in the middle. The paper shows what earning that costs. Weights are preshuffled offline into contiguous 1,536-byte records arranged in matrix-instruction lane order. Activation tiles arrive through direct-to-LDS loads that bypass the register file. Scales are grouped by output tile so each lane fetches them with a single 12-byte load per K-tile. That is hand-written kernel engineering against a specific instruction set, and it is why a vendor announcing support for a datatype and a vendor shipping a competitive kernel for it are two different announcements.
Now hold that against the measured numbers instead of the peak ones. Across all supported linear layers on two production ads ranking models, the authors measure GEMM kernel speedups over FP16 of 1.73x to 1.99x for MXFP6, with up to 2.90x on individual layers. End to end throughput over their existing FP8 configuration ran 1.5% to 5.3% on Model A and 7.6% to 14.3% on Model B. Peak says four times. The kernel says roughly 1.8 times on the layers actually converted. The system says single digits to low double digits. Those three numbers are all true at once, and the gap between them is the reason a peak spec sheet is not procurement evidence.
One more piece of context, because it explains the urgency. According to Tom's Hardware on November 16, 2026, Anthropic says Claude Mythos Preview cut bringing a model up on AMD Instinct MI355X GPUs from as long as twelve months to about three days. Twelve months of specialist kernel work was the natural rate limiter on new silicon. A weekend is not a rate limiter at all. Hardware and tooling now move faster than the review checklist that is supposed to catch them.
THE FORMAT-CHANGE PROTOCOL
Here is the framework. Call it Freeze, Re-Audit, Ship, and run it every time a serving format changes.
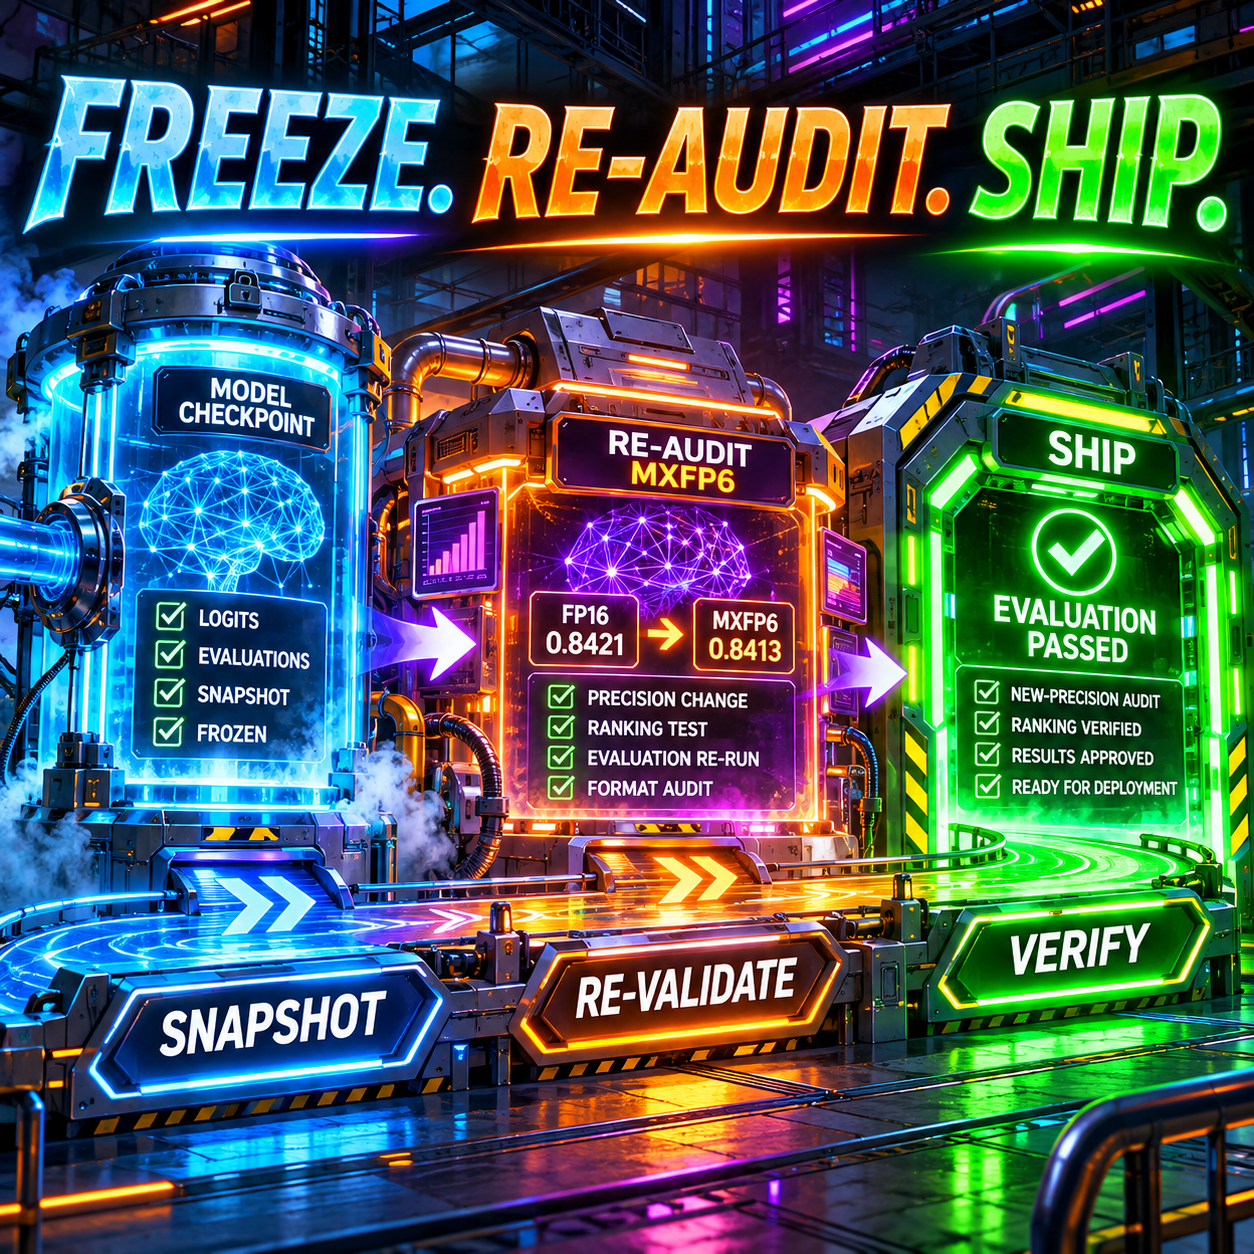
- FREEZE. Snapshot the reference checkpoint and its eval outputs before anything else moves. Store logits, not only the metrics, because you will need to re-derive a metric you did not know you needed. Bind the snapshot to a fixed data slice with a fixed seed so that the only variable left in the next comparison is the format.
- RE-AUDIT. Run the ranking audit, the detector audit, or the launch gate at the new precision, on that same slice. If the audit was built against FP16 assumptions, rebuild the audit first. An epsilon tuned around FP16 rounding, a labeler that assumes a precision-dependent score distribution, a detector with a sampling budget set for a bigger model: each one is a measurement whose error floor was calibrated for a format you no longer run.
- THEN CLAIM. Only after the audit returns at the new precision does anyone get to say the model held. A pass at the old format is a statement about the old format.
The trap is the green checkmark. Every team that changed a format and kept the harness got a green checkmark, because a harness calibrated to the old error floor does not have the resolution to fail. It returns the number it returned last quarter and the reviewer reads stability as safety. That is the whole failure mode in one sentence: you did not measure the model, you measured the instrument.
The paper gives a useful contrast for how an audit is supposed to look. Its MXFP6 replacement rules cover 80.8% of Model A's linear-layer weights and 72.9% of Model B's, and the accuracy result is reported per task rather than as one aggregate: all six tasks inside the 0.01% NE tolerance for Model A, all three inside it for Model B. The sign-off is not a single averaged number. It is a check that had to hold at every site where the format was applied.
The paper also reports the price the format pays at the layer level. On the most compute-intensive layers, MXFP6 gives up a median of 1.2 to 1.8 dB of QSNR per call site against FP8 and MXFP8, where QSNR is the quantization signal to noise ratio, the decibel gap between a tensor's original signal and the error the format introduces, and buys 26% to 40% more GEMM throughput in exchange. Keep both halves of that trade in view, because together they are the argument for why a QSNR table cannot approve a launch. QSNR is a per-tensor signal quality measure. NE is the product outcome. One layer can lose 1.5 dB and cost nothing measurable, and another can lose less and flip a ranking. Only the audit tells you which one you are standing in front of.
This is the third note in a short series circling the same point. "Your Quantization Is Wrong: Per-Layer Precision Cuts Inference Energy 23%" made the case that precision belongs to the layer, because the energy bill is per layer. "Your 4-Bit Model Just Beat Its Full-Precision Original. The Compress-Then-Heal Pipeline Is Broken." made the case that a healing pass can leave you quietly below your own reference and nobody checks. This one is the launch gate. Once precision becomes per-layer, per-shape, and chosen against a hardware instruction set, the only thing standing between you and a shipped regression is whether the audit ran at the precision you shipped.
WHAT THIS MEANS FOR YOUR STACK
If you serve ranking or recommendation models, your launch bar is 0.01% NE and a format change is a re-validation event, not a config flag. The scale context is what makes this unavoidable: Meta's most complex late-stage ranking model reached about 22.2 times the inference work per example in the first half of 2026 against its first half of 2024 level, with 33.3 times that same starting point targeted for the second half. You do not pay for a 33 times increase with more GPUs alone. At some point the arithmetic per element has to get cheaper, which means the format becomes a first-class part of the architecture instead of a compression choice made once and forgotten.
If you serve LLMs, you have headroom on the headline metric and none guaranteed on the detectors around it. A reproducible audit published in August 2026 ran four hallucination detectors on Llama-3.2-3B-Instruct and Qwen2.5-3B-Instruct at 4-bit NF4 on a single Colab T4 and found that cross-model ranking transfer is poor enough to invert: Spearman rho of -0.80 and Kendall tau-b of -0.667. The cheap lexical n-gram baseline was statistically indistinguishable from semantic entropy and SelfCheckGPT-NLI under bootstrap confidence intervals. The same audit also caught a second failure mode worth memorizing. On TruthfulQA, a token-overlap-to-multiple-choice correctness labeler produced near-chance AUROC of 0.46 to 0.59 for all four detectors, while those same detectors reached 0.69 to 0.89 on TriviaQA through an identical pipeline. A near-chance number looks exactly like a broken detector and was actually a broken labeler. Change the format and your safety metric collapses, and you now have two hypotheses to test with no way to separate them unless you froze reference outputs first.
If you build agentic systems, the bar is tighter than it looks and it lands somewhere you may not have instrumented. An agent is a loop of model calls wrapped in routers and rankers: a controller that picks the next tool, a small classifier that chooses which retrieval path or API to invoke, a scorer that decides whether a step succeeded. Those are ranking models, and they are routinely quantized separately from the model in the middle of the loop, often harder and often later. A rank flip in that router does not produce a worse sentence. It produces a different plan. Ten steps later the agent has called the wrong tool, written to the wrong record, and reported success, and the transcript reads coherent the whole way. Silent task failure is the agentic form of a score flip, and it happens long before the final token is generated.
If you are procuring silicon, change the question you ask. Ask for native-format GEMM benchmarks at your layer shapes and your batch sizes, not dequantized proxies. Ask for amortized bits per element including scale storage, which is 6.25 for MXFP6 rather than 6. Ask what fraction of the linear layers the vendor's kernels actually support, since 80.8% is a real number and 100% is a claim. Ask for measured QPS beside peak PFLOPs, and treat the ratio between them as the vendor's true efficiency disclosure.
WHAT TO DO TODAY
- Inventory every model in production whose evaluation predates its current serving precision. That list is your exposure.
- Freeze reference outputs and logits for your top three ranking models this week, on a fixed data slice with a fixed seed.
- Add a mandatory "format changed?" checkbox to launch review, and make the audit result at the new precision the evidence attached to it.
- Re-run your hallucination and safety detectors after any quantization change, and re-validate the labeler in the same pass, not just the detector.
- Ask your silicon vendor whether MXFP6 or an equivalent 6-bit microscaling format is native on your target part, and what fraction of layers their kernel stack covers.
THE UNCOMFORTABLE QUESTION
When your next launch review signs off on a quantized model, will anyone in the room be able to say which eval actually ran at the new precision, or will the deciding evidence be a green checkmark that nobody can date?
Get More Articles Like This
Getting your AI agent setup right is just the start. I'm documenting every mistake, fix, and lesson learned as I build PhantomByte.
Subscribe to receive updates when we publish new content. No spam, just real lessons from the trenches.
Build Real AI Infrastructure
PhantomByte teaches you to build real AI infrastructure yourself: local AI stacks, autonomous agents, multi-agent orchestration, web scraping, and custom tools. Step-by-step PDF tutorials you download, follow, and deploy. No subscriptions. No fluff. Just skills that ship.