NVIDIA put a price on reproducibility this month, and the price is about 2 percent. That is the steady-state overhead of holding bitwise determinism across an 800-step training run on 2,432 GPUs, measured on a trillion-parameter Nemotron model. The same work carried roughly 17 percent overhead before the optimizations landed. Bitwise determinism means the same inputs produce bit-for-bit identical outputs on every run, so an independent run and a checkpoint-resumed run follow one identical trajectory.
The number is not a marketing deck talking. It sits in a technical post NVIDIA published on October 6, 2026, and the workflow behind it is proposed in Megatron-LM pull request 7262, opened by Zhiyu Li on September 11, 2026 and still marked draft.
Here is the thesis, stated plainly. At trillion-parameter scale, an unreproducible run is an undebuggable run, and the industry just lost its last excuse for shipping one. This is the same lesson as PhantomByte #201, "Your Cluster Is Interconnect-Bound, Not Compute-Bound." You measured your cluster and learned the wire was your bottleneck, not the silicon. Same discipline, different bottleneck. Now measure whether your runs can be replayed at all.
WHAT THE DETERMINISM TAX ACTUALLY IS
The determinism tax is the extra compute and engineering you pay to make every rank produce bit-for-bit identical results. You pay it because nondeterministic reductions run faster, parallelism is easier without ordering constraints, and runtime autotuning picks whatever kernel runs fastest on the day.
That trade stays invisible until a run dies at step 40,000. Then you cannot replay the failure, cannot bisect the loss spike, and cannot prove the fix worked rather than just moved the noise.
NVIDIA's numbers show how small the tax becomes when you attack it. The Nemotron 3 Ultra workload fell from roughly 17 percent overhead to 2 percent after a buffer-fill optimization, then to 1.5 percent at 3,072 GPUs. A hybrid Triton proxy started near 60 percent, dropped to 37 percent after restoring a fused MoE-MLP path, then reached 2 percent. At 2,432 GPUs the production recipe settled near 2 percent, holding bitwise determinism across 800 steps.
Put the formula in your runbook. Determinism tax equals deterministic step time divided by baseline step time, minus one, times 100 percent. The baseline is the fastest supported nondeterministic recipe on the same model, hardware, batch sizes, parallelism and precision, measured only after performance stabilizes. Two percent is a rounding error against the cost of losing a trillion-parameter run.
HOW THE FINGERPRINT METHOD WORKS
Two runs that print the same rounded loss are not identical. They can agree on the printed number and disagree in the lower-order bits of their gradients, which is why teams argue about nondeterminism instead of fixing it.
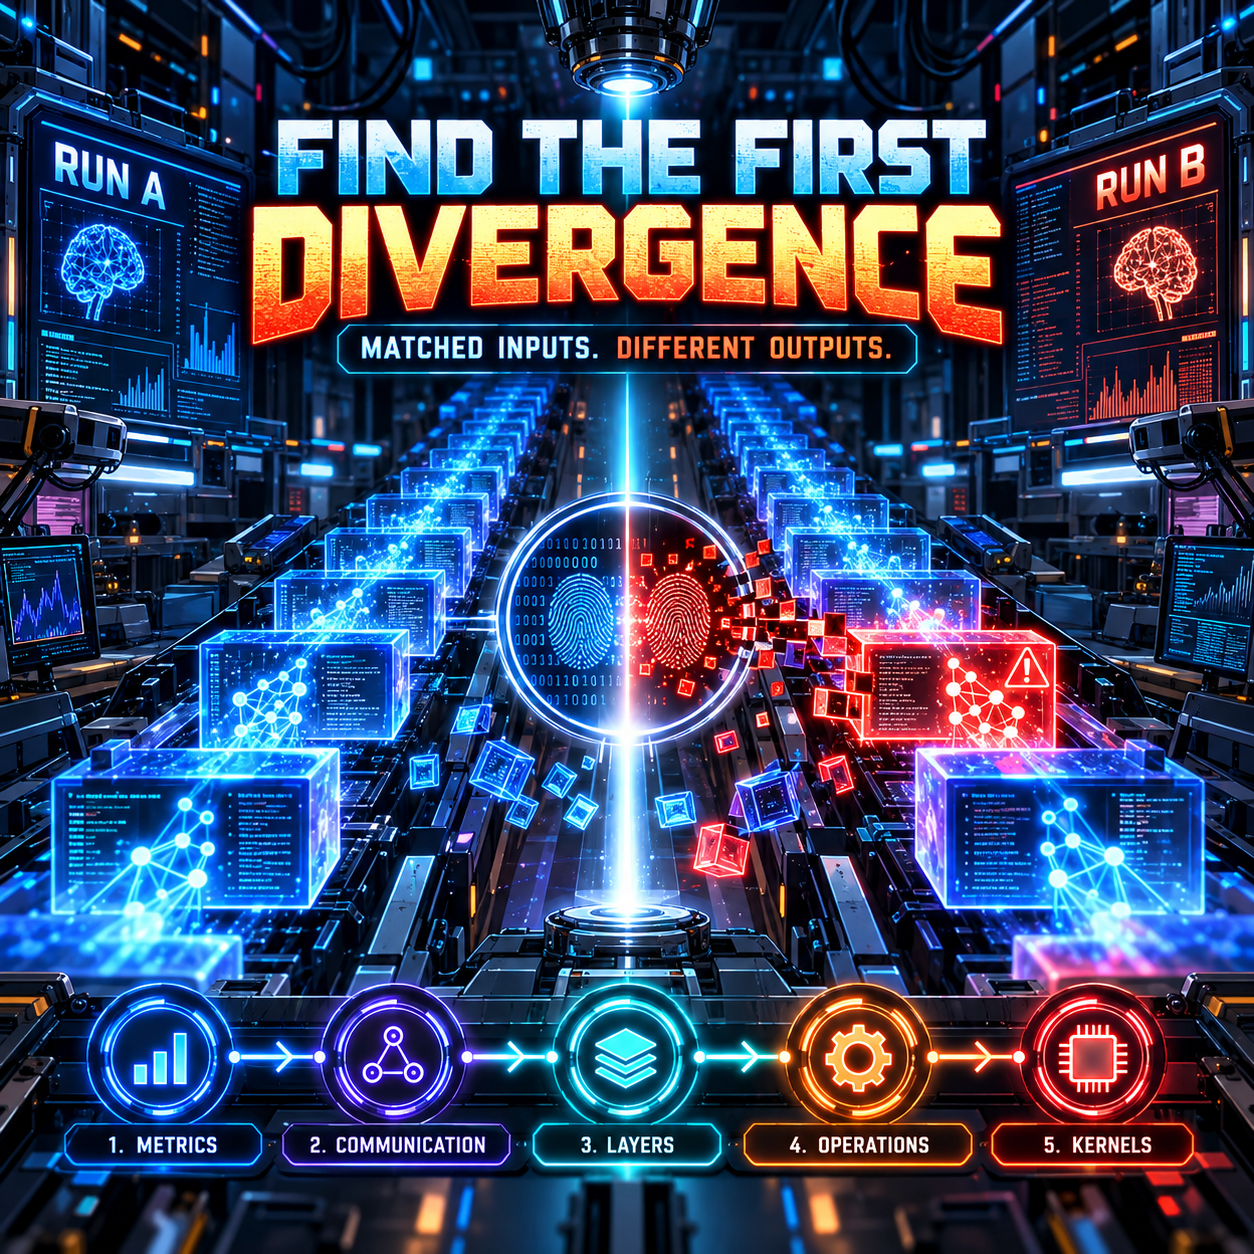
The method in PR 7262 records an ordered, per-rank fingerprint stream, writes each rank's trace to its own file with no added collectives or cross-rank ordering, and diffs the two streams offline. The first record whose output differs while its inputs matched is the root cause. Everything before that record matched byte for byte, so no hypothesis is needed, and forming one before that record is in hand is the most common way these investigations go wrong.
The capture ladder narrows the search in five rungs.
- End-to-end metrics find the first iteration where a serialized metric differs.
- Broad semantic tracing covers collectives, pipeline communication, recomputation and gradient reductions.
- Module and layer tracing goes down to a transformer layer, an MoE block or an optimizer stage.
- Operation-level tracing fingerprints ATen operations and finds the first op with matching inputs and different outputs.
- Kernel-level tools name the responsible kernel and the mechanism inside it.
Read the result with three rules.
- Inputs match and outputs differ means that rank is a candidate origin, so investigate that operation or its hidden producer.
- Both differ means that rank is a downstream receiver, so keep tracing upstream.
- No origin on any traced rank means the origin sits outside your capture, so widen the window or the rank set.
Most teams treat nondeterminism as weather. Fingerprinting turns it into a lab result, with a rank, a step and an operation number attached.
NVIDIA fingerprints GPU-resident tensors with torch.hash_tensor and records each tensor's shape, dtype and element count with the digest. For MXFP8 and NVFP4 tensors, fingerprint the encoded values and the scale buffers. One detail is worth memorizing. A whole-tensor XOR fingerprint cannot see a permutation, because XOR over any permutation of a sequence comes out identical, so routing maps and MoE dispatch outputs need the dim argument and get fingerprinted by row or chunk.
Two kernel-level fixes did the real work. In the grouped-GEMM epilogue, multiple N-tiles were accumulating into the same dprob[token] address, so the result depended on arrival order. The fix gives each N-tile a private output slot, keeps parallel execution inside the kernel, and combines the slots in a fixed order. The second pins a fixed reduction order so parallel math still commutes to the same bits.
False alarms are part of the job. TorchDispatchMode only sees ATen operations routed through the dispatcher, so a first mismatch at a plain view or slice means you probe the custom kernel that produced its input. Uninitialized tensors and incomplete asynchronous collectives can read before their contents are valid, so exclude those first.
WHY NOW: THE SCALE ARGUMENT
The bigger the run, the more determinism is worth. Failure replay, loss-spike bisection, validating a system change, and resuming an interrupted run all assume you can make the same thing happen twice.
NVIDIA runs the arithmetic. For a hypothetical 100-day nondeterministic baseline on 10,000 GPUs, cutting overhead from 15 percent to 5 percent saves 10 days, which is 100,000 GPU-days.
The transport layer underneath moved the same day. NVIDIA published DOCA GPUNetIO on October 6, 2026, a unified GDA-KI foundation that lets CUDA kernels drive Ethernet, RDMA, Verbs and DMA operations directly while keeping the CPU off the critical path. NCCL, NVSHMEM, UCX and NIXL, and the Holoscan Sensor Bridge now build on that one foundation. When every collective rides one stack, a change in that stack is a reproducibility event, which is exactly what fingerprinting catches.
Now follow the money, because the money is what pays for every layer you just read about, and it is written on terms that assume the stack works. NVIDIA's 2Q fiscal 2027 10-Q disclosed $530 billion of gross off-balance-sheet guarantees across six line items, up from $184 billion the prior quarter, according to SemiAnalysis. Supply and capacity commitments rose from $119 billion to $279 billion. Guarantees on SB Energy's PORTS-Pike campus in Ohio rose from $3.5 billion to $108.5 billion, and that line covers 4.25 IT-GW leased to OpenAI for twenty years, land, power and shell guaranteed by NVIDIA. The $530 billion sits against $91 billion of on-balance-sheet liabilities, including $33.4 billion of total debt.
Capital that patient does not accept "we think the fix worked" as a status report.
THE SAME DISCIPLINE AT THE OTHER END OF THE LIFECYCLE
Training fingerprints and production traces are one discipline at two ends of the same pipeline. Netflix rebuilt observability for a system producing 38 million events per second, and the QCon talk by Prasanna Vijayanathan and Renzo Sanchez-Silva is now public on InfoQ. Netflix replaced reactive monitoring with an AI-driven operational ontology and agentic workflows built on Claude and graph databases. The core move unifies metrics, events, logs and traces into one queryable knowledge graph instead of silos humans correlate by hand.
Their lesson transfers directly. The ontology, not the model, determines whether automated diagnosis produces a real answer.
Carry this framework into your own stack. Reproducibility is a ladder. Deterministic training is the bottom rung. Traced, replayable execution is the middle. Queryable evidence is on top. Each rung is only as trustworthy as the one below it, so a team that cannot reproduce a training run should not be automating its diagnosis. Teams that skip the bottom rung cannot climb the rest.
This is where the argument stops being philosophy for anyone shipping agents. An autonomous debugging agent or a root-cause loop reads telemetry and acts on it, which means it needs deterministic ground truth to reason over. Point an agent at a metric that moves on every rerun and it will treat nondeterminism as a regression, chase a cause that is not there, and hand you a confident root cause that does not exist. Deterministic training and the ordered fingerprint stream are what give that agent something stable to read, and that is why the bottom rung of the ladder is the one agentic reliability is standing on.
WHAT TO DO TODAY
- Pull your last three failed training runs and answer one question. Could you replay any of them bit for bit? If no, you have found your real debugging ceiling.
- Read Megatron-LM PR 7262. The fingerprint method is open and portable to any large-scale trainer, not only Megatron.
- Measure your actual determinism tax before assuming it is expensive. NVIDIA's roughly 2 percent at 2,432 GPUs sets the reference point, and yours may be lower.
- Audit your two documented divergence sources. Reduction order and grouped-GEMM writes are where the published nondeterminism lived, and both have a deterministic path.
- Add a determinism gate to your regression suite. Recipe validation through deterministic mode, kernel tests that repeat operations with identical inputs and RNG state and compare byte for byte, and module validation across parallelism configurations including FP8 and FP4.
THE UNCOMFORTABLE QUESTION
You are spending hundreds of millions on GPUs to train a model once. What exactly are you paying to make sure you could do it twice?
Get More Articles Like This
Getting your AI agent setup right is just the start. I'm documenting every mistake, fix, and lesson learned as I build PhantomByte.
Subscribe to receive updates when we publish new content. No spam, just real lessons from the trenches.
Build Real AI Infrastructure
PhantomByte teaches you to build real AI infrastructure yourself: local AI stacks, autonomous agents, multi-agent orchestration, web scraping, and custom tools. Step-by-step PDF tutorials you download, follow, and deploy. No subscriptions. No fluff. Just skills that ship.