Your GPUs spend part of every layer waiting on a phone call. In tensor-parallel training, every layer ends with an all-reduce: each GPU ships its partial results to every other GPU, and every GPU sums them before anyone can move on. That call sits between two dependent matrix multiplications, so its cost cannot be hidden. As compute gets faster than interconnect, the wait gets worse, not better.
The obvious fix is to shrink the payload. Send 4-bit values instead of 16-bit and the wire cost drops nearly 4x. The catch is that an all-reduce has to add the values it carries, and rounding that sum injects error at every single call, thousands of times per training step. Do it naively and the errors accumulate across layers until your model is garbage. This is why almost nobody ships 4-bit collectives.
A paper called Echo (arXiv 2610.14277) just showed the way through, and the mechanism is the kind of counterintuitive invariant PhantomByte exists for: let every rounding error cancel itself.
THE PART OF YOUR STACK NOBODY PROFILES
You profile FLOPS. You profile tokens per watt, and we covered that. You audit your wires, which we did in "Your Cluster Is Interconnect-Bound, Not Compute-Bound." Almost nobody profiles the all-reduce itself, the single operation that makes tensor parallelism expensive.
Start with the definitions, because the whole argument hangs on them. Tensor parallelism means splitting one layer's matrix multiplications across multiple GPUs. An all-reduce is the synchronization step where every GPU exchanges and sums its partial results.
The paper's own framing of why that step is special is worth repeating. Tensor parallelism splits the weight matrices of every attention and MLP layer across several GPUs, and each GPU computes a partial result from its share of the weights. Turning those partial results into the layer output requires an all-reduce, a collective that adds the partial results from all GPUs and returns the sum to each of them. The all-reduce then runs between two dependent matrix multiplications, so it is a synchronization barrier on the critical path.
Contrast it with the collectives you are used to hiding. The gradient all-reduce of data parallelism runs during the backward pass. The point-to-point transfers of pipeline parallelism are pipelined across microbatches. Neither sits between two dependent matmuls the way the tensor-parallel all-reduce does, so neither is unhideable in the same way. Overlap can hide part of it. It cannot hide the dependency.
The stakes sit one layer below the GPUs. The same logic that makes the grid the gate on new capacity runs one level down, at the wires between your GPUs, where the binding resource is bandwidth rather than megawatts. Marsden Hanna, Google's head of energy and sustainability policy, told Politico's Energy podcast that grid congestion is the biggest challenge for data center growth, with utilities telling the company that grid-connected service can take five years, sometimes ten. The constraint moved to the wires in more ways than one, and the wire you can control is the one between your accelerators.
WHY YOU CANNOT JUST SEND 4 BITS
Walk the naive approach to its failure and the fix lands cleanly. An all-reduce must sum the values it carries. Quantize the payload to 4 bits before that sum and you cut the wire cost nearly 4x, but every call now injects a rounding error. One call is noise. Thousands of calls across hundreds of layers is accumulated drift, and it is the accumulation, not any single rounding, that determines model quality.
Here is the baseline you are measuring against. NCCL is NVIDIA's collective communication library, and it is what most stacks call when a tensor-parallel layer reaches its barrier. It moves those partial results at 16 bits.
Think about the arithmetic of that error for a second, because it is the whole reason the problem sat unsolved. Rounding on a single collective is bounded and tiny, close to noise. What breaks a model is not one rounding. It is hundreds of roundings, one per layer, each added to the value the next layer inherits, so the deviation compounds across depth rather than averaging out. The honest read of the literature before Echo is that almost everyone treated each call in isolation, which is exactly the wrong frame when the damage is cumulative. Fix one call's rounding and you have fixed nothing.
THE CANCELLATION RULE
Echo's mechanism is three moves, and you can hold all three in your head at once.
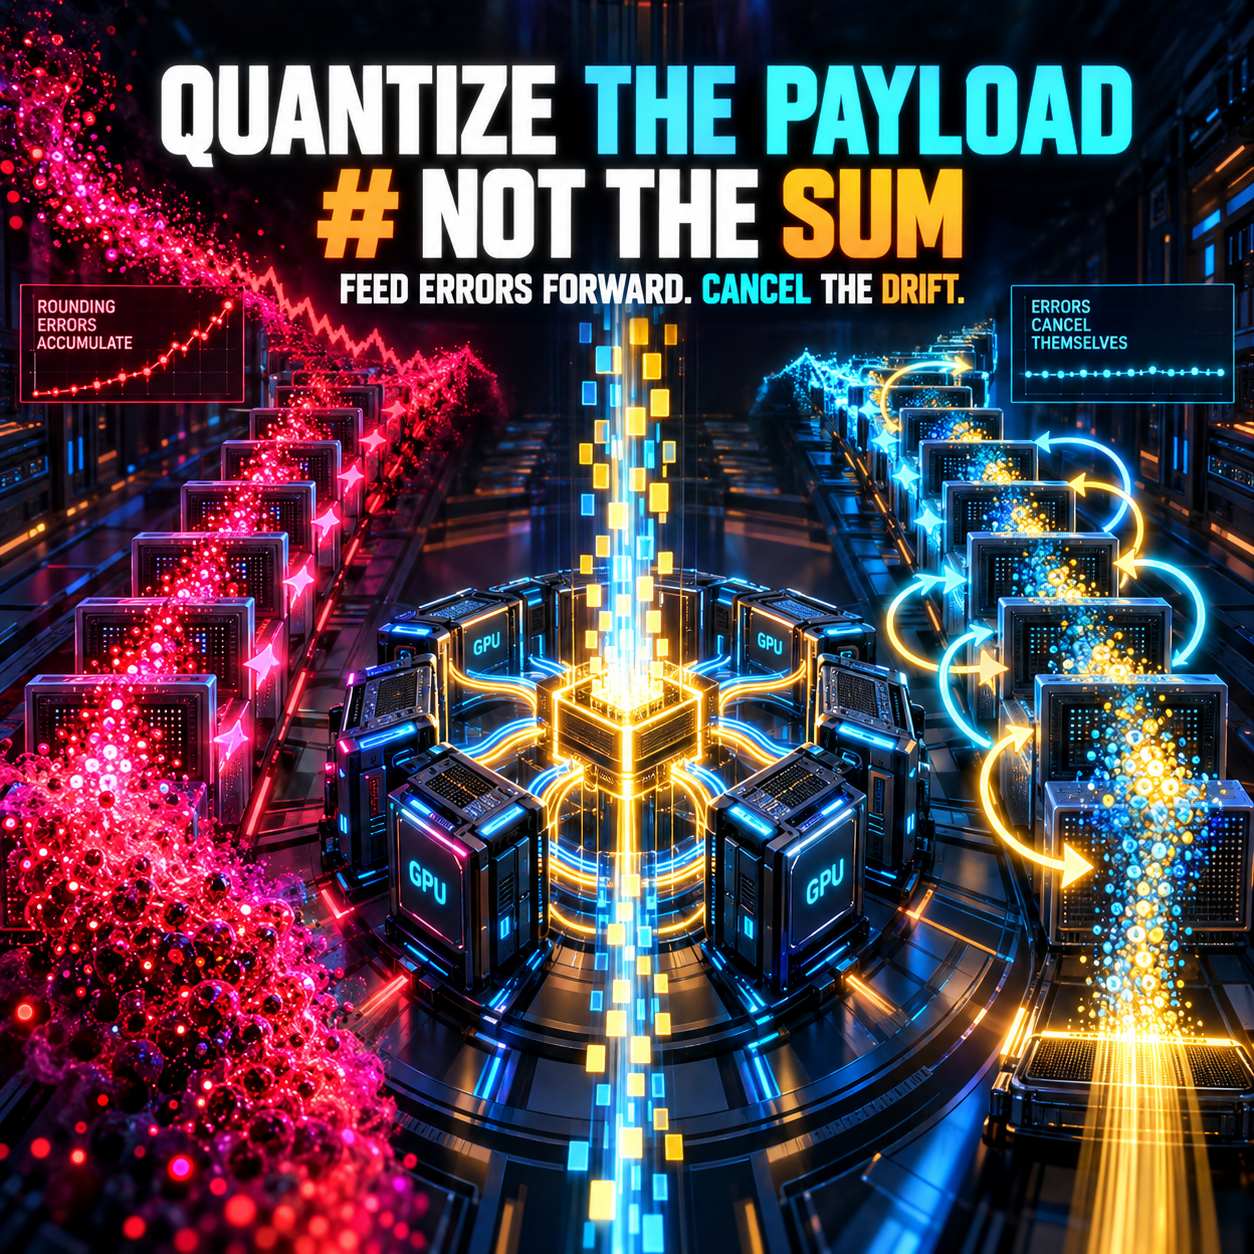
First, move data in 4 bits and sum in high precision. The payload is small, but the arithmetic is exact at the one point where exactness matters, which is the sum itself.
Second, quantize each value at most twice per call regardless of how many GPUs participate. In the concrete design, one owning GPU forms the sum in high precision and a quantized all-gather returns the reduced segments, so each element is quantized at most twice per call. That bound does not grow with the number of GPUs, which is the part that keeps the error budget from exploding as you scale out.
Third, feed each injected error forward. The reduction step reveals each rounding error exactly, and a two-timescale compensator feeds it back into subsequent calls, so old errors cancel instead of accumulating. The paper fuses that compensator into the entry pass of the all-reduce plus an update that runs beside the next matrix multiplication, without changing the computed values. The name comes from this mechanism: each injected error returns to the collective at the calls that follow, like an echo.
Then the payoff. The authors prove that the accumulated error stays bounded independently of depth, and that the guarantee is free of the exponential Lipschitz factor that shows up in worst-case bounds. That is the citable invariant. State it as a named decision rule you can carry into a design review: quantize the payload, never the sum; feed every error forward so it cancels downstream.
One more implementation detail matters for anyone who does not own FP8 or FP4 silicon. Echo transports 4-bit integers with half-precision quantization parameters per group and needs no FP8 or FP4 hardware support. The trick is numerical, not a new accelerator.
WHAT THE NUMBERS ACTUALLY SAY
Ground every claim in the paper's measurements, because this is the section an infrastructure review will attack. On A100 GPUs, Echo is 2.09x faster than the 16-bit NCCL all-reduce on 1 GB messages. It speeds up time to first token by up to 1.16x and the training step by up to 1.09x on an idle interconnect, and by up to 1.44x and 1.38x as background traffic grows.
Quality is where the argument is won or lost, and this is the part most quantization results skip. Echo keeps average accuracy across seven benchmarks within 0.4 points of 16-bit inference on Qwen3-8B. In 10B-token pretraining, its final loss lands less than 0.9% above 16-bit training.
Now the blunt paragraph. The collective is only part of the step, so the 2.09x on the all-reduce does not become 2.09x on your job. The end-to-end gains are the 1.09x to 1.16x figures on an idle link, and they get better under load, at 1.44x and 1.38x, because a busier interconnect is exactly where a smaller payload pays more. Anyone promising you a 2x training run from a 4-bit collective is selling something the paper did not claim.
WHEN 4-BIT COLLECTIVES ARE SAFE: A DECISION RUBRIC
Give the decision three gates, and require all three before you touch production.
| Gate | The test |
|---|---|
| Gate one | Is your workload tensor-parallel with large messages? The 2.09x was measured on 1 GB messages. Shrink the message and the win shrinks with it, so small collectives need not apply. |
| Gate two | Is the interconnect the binding constraint? If your job is compute-bound, a faster collective buys you almost nothing, and you should fix the compute bottleneck first. This is the same instinct as the wire audit: measure before you spend. |
| Gate three | Can you measure accuracy drift against a 16-bit baseline before you commit? The 0.4-point result is one model on one benchmark set. Your stack is not Qwen3-8B, so your number has to be your number. |
If all three gates pass, pilot it on one job and diff the eval against your baseline. If any gate fails, keep 16-bit collectives and stop paying the 4x only where it is actually 4x.
WHAT TO DO TODAY
- Measure, do not assume. Instrument one training or serving job and record what fraction of step time is spent in NCCL collectives. If you do not know this number, you do not know if this article applies to you.
- Pull the Echo paper (arXiv 2610.14277) and read the error-bound proof in Section 6. It is the part your infrastructure review will ask about.
- Run one baseline eval on your current 16-bit pipeline so any future 4-bit collective pilot has something to diff against.
- Check whether your message sizes are even in the regime where the 2.09x was measured, the 1 GB class. Below that, the win shrinks.
- Bookmark the distinction this note adds to the PhantomByte stack: 4-bit weights ("Your 4-Bit Model Just Beat Its Full-Precision Original. The Compress-Then-Heal Pipeline Is Broken."), interconnect wiring ("Your Cluster Is Interconnect-Bound, Not Compute-Bound"), and now 4-bit messages. Three different layers, three different decisions.
THE UNCOMFORTABLE QUESTION
You bought the fastest interconnect money can buy and then sent 16 bits where 4 would do, because nobody on your team could prove the errors would cancel. Somebody just proved it. What is your excuse now, the wire budget or the review schedule?
The 4x is not a law of interconnect. It is a decision you have not made yet.
Get More Articles Like This
Getting your AI agent setup right is just the start. I'm documenting every mistake, fix, and lesson learned as I build PhantomByte.
Subscribe to receive updates when we publish new content. No spam, just real lessons from the trenches.
Build Real AI Infrastructure
PhantomByte teaches you to build real AI infrastructure yourself: local AI stacks, autonomous agents, multi-agent orchestration, web scraping, and custom tools. Step-by-step PDF tutorials you download, follow, and deploy. No subscriptions. No fluff. Just skills that ship.