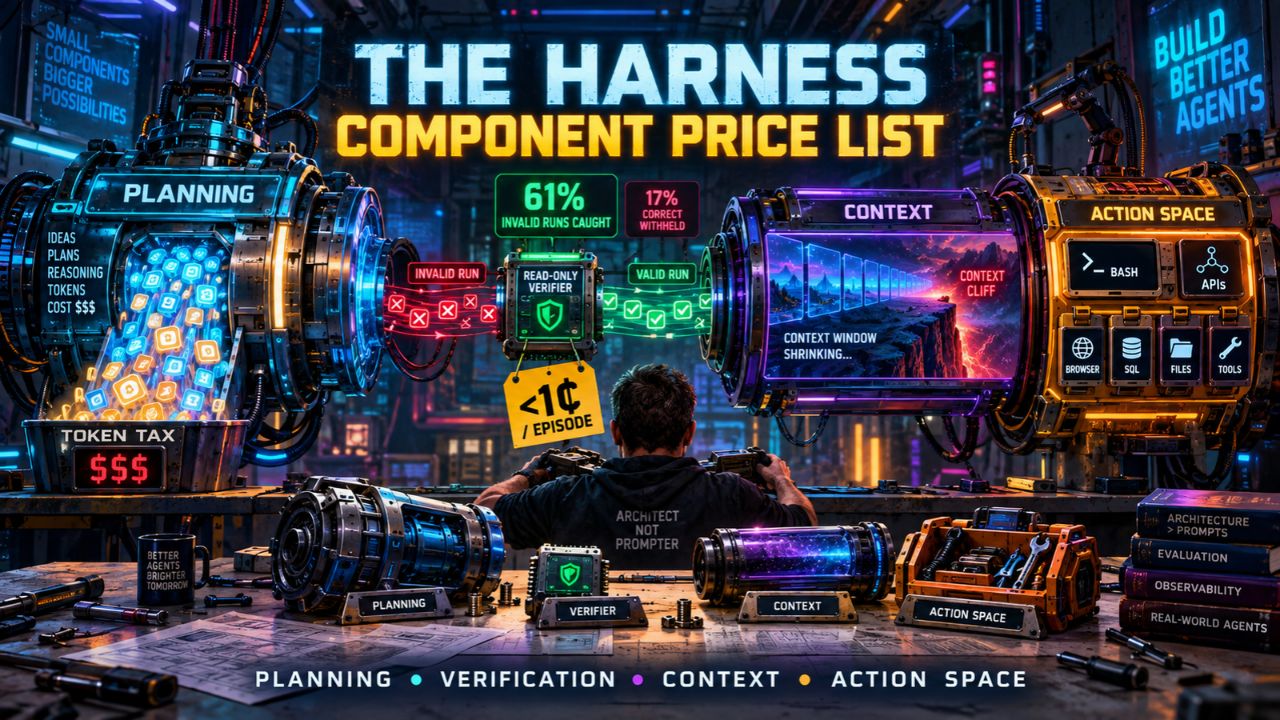
Two papers landed on the same day, September 17, 2026, and together they did something the agent tooling market keeps avoiding. They priced the parts of an agent harness separately.
One team ran 265 matched cells and found that prewritten task-specific plans beat shuffled policy text, matched on word count, by 7.17 percentage points. The other ran 176 matched settings across four models and found planning flips from an accuracy scaffold to a cost saver depending on the model sitting underneath it.
Your harness is not one product. It is a bundle of components with different prices and different payoffs, and you are probably paying for planning you do not need while skipping a verifier that costs less than a cent per episode.
PhantomByte note #184 made the first half of this argument. The evaluation harness moved benchmark scores 4.3 times more than the training recipe did. This article finishes that thought. It prices the harness's own components against each other.
THE EXPERIMENT THAT SEPARATES PLANNING CONTENT FROM PADDING
The first paper is arXiv 2609.20474, "How Do Agent Harnesses Create Value? Planning Information and Release Control in Stateful LLM Agents," by Yukun Zhang, Kemu Xu, and Yishen Chen. It ran two Retail experiments plus an Airline pilot inside tau-squared-bench.
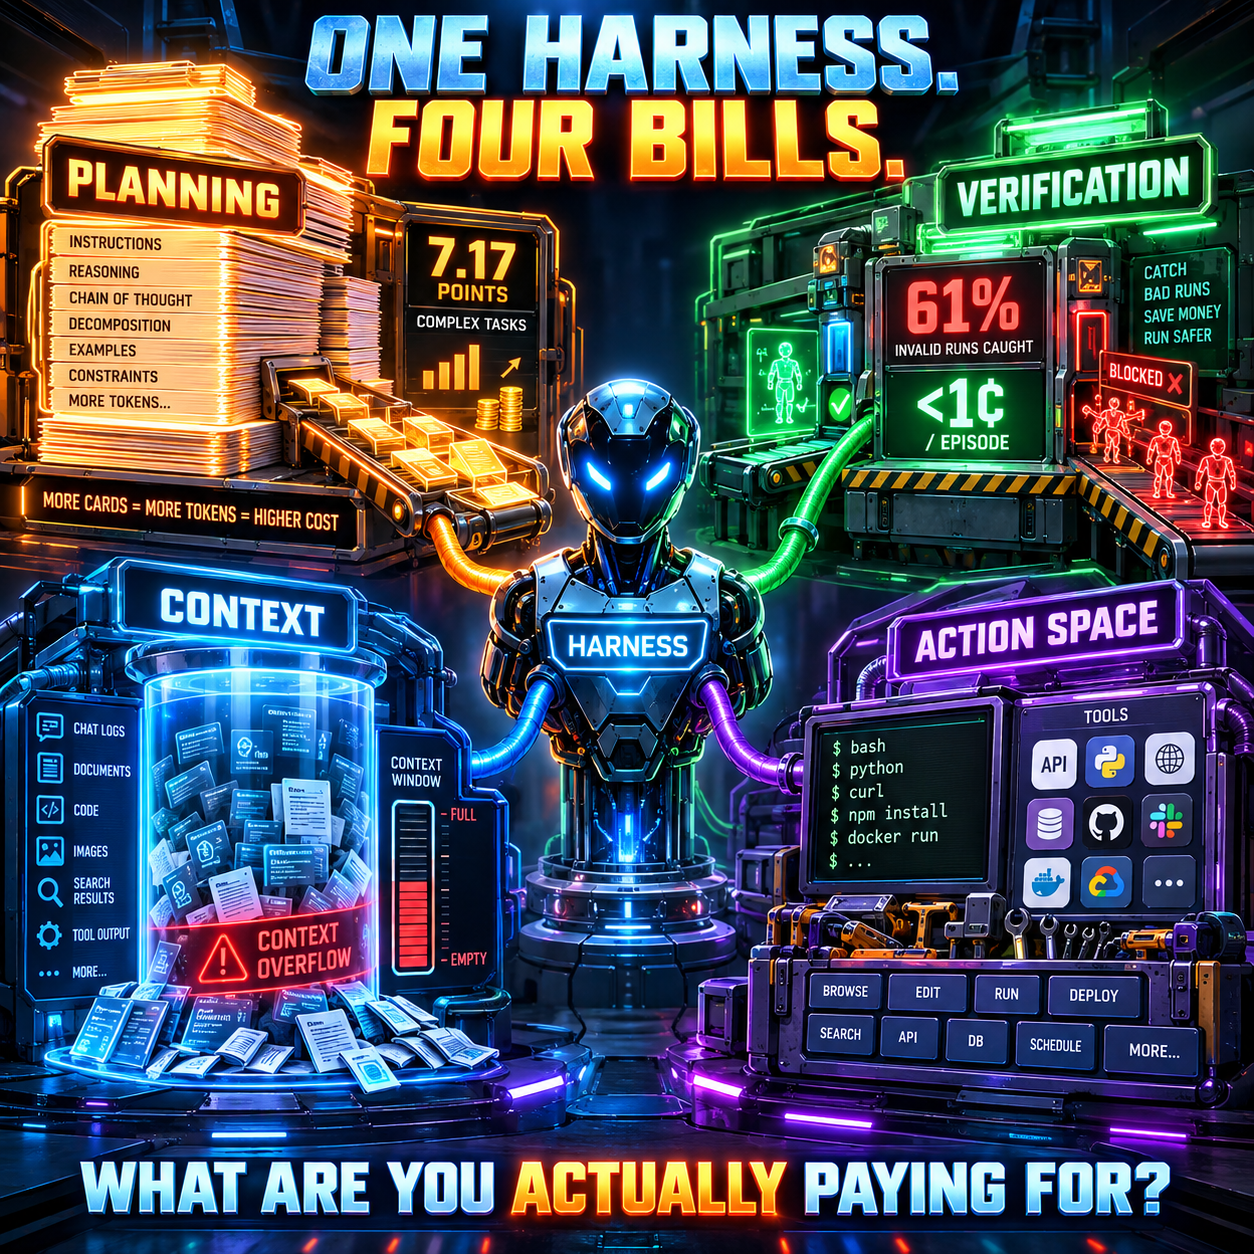
Here is the trick worth copying. They compared prewritten task-specific plans, which they label Fixed, against shuffled policy text matched on word count, which they label Sham. Same prompt length. Same token budget. Different content.
That control is the entire experiment. It separates "planning guidance is valuable" from "any planning-shaped text is valuable." Most harness evaluations never make that distinction, so they credit planning for gains that any long prompt of the same size would have produced.
The result across 265 matched cells is a 7.17 percentage point improvement in oracle-verified success for Fixed over Sham. The 90 percent task-clustered bootstrap interval runs from 1.15 to 13.36 points. Gains concentrate in higher-complexity tasks.
Read the interval before you quote the average. A 7.17 point gain with a lower bound barely above one point means simple tasks give you almost nothing and complex tasks carry the whole effect. If your workload is mostly simple, the planning prompt is not doing the work you think it is doing.
That raises the obvious operational question: how do you know which bucket your tasks fall into? You need a complexity metric you can compute in production, not a feeling. Three signals do most of the work. Count the distinct tool calls a task requires, because a task that touches one endpoint is not the same shape as one that spans four systems. Count the number of decision points where the correct next step depends on the result of the previous one, since serial dependency is what makes a task long-horizon. Then track the historical failure rate for that task class in your own logs, because tasks your agent already solves are not complex for your harness no matter how they look on paper. Bucket tasks as low, medium, and high against those three numbers, rerun the planning ablation inside each bucket, and you will find your own version of the paper's result. Most teams discover that a thin slice of high-complexity work carries nearly all of the planning benefit, and everything below it is paying for text that changes nothing.
Word-count matching is a reusable pattern. Any time you add instruction text to a prompt and claim the text caused the improvement, a shuffled control of identical length is the cheapest way to find out whether you are measuring content or volume. It costs you one extra arm in the eval and it settles the argument.
One scope note before you generalize. The paper's headline numbers come from tau-squared-bench task families, mostly Retail with an Airline pilot. Treat the mechanism as portable and the exact point estimate as task-specific until you reproduce it on your own workload.
THE VERIFIER: LESS THAN A CENT PER EPISODE
The same paper priced the second component. A read-only terminal verifier rejects 61 percent of Retail oracle-invalid episodes while withholding 17 percent of correct ones, at less than one cent of additional cost per episode.
Both numbers matter. The 61 percent is the catch rate. The 17 percent is what you pay in blocked good runs. A component that reports a catch rate without a withholding rate is marketing, not engineering.
Those blocked runs need a policy, and the policy is cheaper than it sounds. The 17 percent figure counts runs the verifier refuses to release, not runs it destroys. Because the verifier only reads, the episode state is still intact when it withholds, so the usual response is to route the blocked episode to a second path: a retry with one adjustment, a narrower re-plan, or a handoff to a human reviewer for the small share of cases that reach production-critical code. A withheld run is a recoverable event, which is exactly what you want from a gate sitting in front of a live pipeline. If you reroute the same episode with no change and the verifier blocks it again, treat the second block as a real signal about the episode rather than noise from the gate.
False-pass cost is the term you need here. Every erroneous acceptance that slips through your harness lands downstream as a wrong commit, a bad deploy, or a customer-visible defect. A verifier at under a cent per episode is cheaper than almost any incident it prevents, and the paper states the cost explicitly.
The buried punchline is the procurement finding. A standalone verifier captures nearly all the false-pass benefit of the full planning-plus-verification stack, at a fraction of its cost. You do not have to buy the bundle to get the protection. You can buy the cheap half and keep most of the value.
Read-only is doing real work in that sentence. A verifier that cannot mutate state has a bounded blast radius, so you can attach it to a live pipeline without granting it write authority. That is why the cost floor stays under a cent.
This connects to PhantomByte note #187, "Your Agent Does Not Know It Is Failing." Agents cannot reliably report their own failure. The verifier is the cheapest instrument you own for catching what the agent will never tell you, and #192, "Your Agent Aced the Task. Run It Five Times and Watch It Fail," shows how much run-level variance sits behind a single passing result.
WHEN PLANNING PAYS AND WHEN IT IS DEAD WEIGHT
The second paper is arXiv 2609.20804, "An Empirical Study of Harness Design for Coding Agents," by Run-Ze Fan and coauthors. They held the execution loop fixed and varied three components: planning, action space, and context management. Four models on SWE-Bench Verified and Terminal-Bench 2.1, 176 matched settings, five context-management strategies, four context-window budgets, plus targeted ablations of planning and action space.
Their planning finding inverts the usual story. Planning serves as an accuracy scaffold for weaker models. On stronger models it becomes a cost saver, with little change in accuracy. The same harness component has opposite value depending on which model sits under it.
The decision rule falls out of that. Strong model plus stable task class means your planning text is mostly a token tax, so cut it and measure. That tax has two parts, and most teams only count one of them. The first is token overhead, the input tokens you pay for on every call. The second is latency, because a planning preamble is prefill work the model has to read before it produces a single useful token, and prefill time adds directly to the end-to-end wall clock on every request. A long planning prompt on a strong model is therefore a double charge: you pay more per call and you wait longer for each one, and both charges land on every request in a pipeline that may run thousands of them. When planning no longer buys accuracy, you are accepting that bill for nothing. Weak model or a task class you have not seen before means planning is the scaffold holding the run together, and cutting it will cost you success.
Notice the second half of the stronger-model result. Planning does not lose value on strong models. It changes sides. It stops buying accuracy and starts buying cost control, which is a different line on a different budget.
The paper's trajectory analysis explains why the components behave differently. Planning changes where trajectories stop. Context management extends execution trajectories without substantially altering agent behavior. Action space changes the granularity at which code gets written. Three components, three mechanisms, one bundle sold as a single line item.
CONTEXT MANAGEMENT ONLY PAYS WHEN THE WINDOW TIGHTENS
The same study found context management becomes increasingly valuable as the context-window budget tightens. Most of the benefit comes from preventing context-overflow failures, not from better summarization.
That distinction changes what you build. If summarization quality were the driver, you would invest in better summarizers. Since overflow prevention is the driver, you invest in making sure the window never fills in the first place.
The strongest overall efficiency came from staging rule-based elision before LLM-based summarization. Making elided content recoverable added machinery that models rarely used and yielded no accuracy gain. That is a feature you can delete today and lose nothing.
Think of this layer as the upstream control on a failure mode you cannot fix downstream. It decides whether you ever reach the Compaction Cliff (#171), where compaction is the place safety rules die. Once you are compacting hard, you are already past the point where configuration would have saved you.
THE HARNESS COMPONENT PRICE LIST
Put the two papers in one table and the procurement decision gets simpler. Every figure below comes from arXiv 2609.20474 (Zhang, Xu, Chen) or arXiv 2609.20804 (Fan and coauthors). Nothing here is my estimate.
| Component | The line items the papers priced |
|---|---|
| Planning |
When it paysWeak models, novel task classes, high-complexity tasks.
What it costsPrompt tokens on every call. Neither paper prices these in dollars, so the cost is real but unquantified.
Number that proves it7.17 percentage points over word-count-matched shuffled text across 265 matched cells, with a 90 percent interval of 1.15 to 13.36 points, concentrated in higher-complexity tasks (2609.20474). Planning shifts from accuracy scaffold to cost saver as model strength rises, with little change in accuracy (2609.20804).
|
| Verification |
When it paysWhenever a wrong acceptance is expensive, which is most production systems.
What it costsLess than one cent of additional cost per episode.
Number that proves itRejects 61 percent of Retail oracle-invalid episodes, withholds 17 percent of correct ones, and a standalone verifier captures nearly all the false-pass benefit of the full planning-plus-verification stack at a fraction of its cost (2609.20474).
|
| Context management |
When it paysAs the context-window budget tightens.
What it costsElision rules staged before summarization, plus the plumbing behind them.
Number that proves itValue rises as the budget tightens across four context-window budgets, and most of the benefit is preventing context-overflow failures rather than better summarization. Rule-based elision staged before LLM summarization gives the strongest efficiency, and recoverable elision adds machinery models rarely use with no accuracy gain (2609.20804).
|
| Action space |
When it paysPredefined tools help models with weaker bash proficiency, while bash-capable models operate effectively with a bash-only interface at substantially lower cost, especially on command-line-centric tasks.
What it costsEngineering time to define and maintain tools you may not need.
Number that proves itThose tool conditions and bash-only conditions were measured inside the same 176 matched settings, and action space changes the granularity at which code is written (2609.20804).
|
Now add the liability axis from the first paper, because it collapses the whole table into one line. At low loss assigned to erroneous acceptance, the planning gain dominates. At high liability, the verifier's avoided false passes dominate.
So the answer to "which component do I buy first" is not a component. It is a question about what a wrong acceptance costs your business. Answer that question honestly and the table fills itself.
WHAT TO DO TODAY
- Pull your harness config and list every planning prompt you inject. Word count them. If your model tier is strong and your task class is stable, cut one and measure.
- Price a read-only terminal verifier against your current false-pass rate. If a wrong acceptance costs you more than a dollar, the under-a-cent verifier is the best trade in your stack.
- Check your context-management settings for recoverable-elision machinery. The paper found models rarely use it and it buys no accuracy.
- Rerun your last 20 failed runs with word-count-matched shuffled planning text. If results barely move, your planning prompt was decoration.
- Rebuild your harness budget as the four-row Component Price List, not as one line item called "framework."
THE UNCOMFORTABLE QUESTION
If a shuffled word-count match gets you most of the way to your planning gains, and a one-cent verifier catches more bad runs than your planning ever prevented, what exactly have you been paying the framework for?
Run the table before you answer.
Get More Articles Like This
Getting your AI agent setup right is just the start. I'm documenting every mistake, fix, and lesson learned as I build PhantomByte.
Subscribe to receive updates when we publish new content. No spam, just real lessons from the trenches.
Build Real AI Infrastructure
PhantomByte teaches you to build real AI infrastructure yourself: local AI stacks, autonomous agents, multi-agent orchestration, web scraping, and custom tools. Step-by-step PDF tutorials you download, follow, and deploy. No subscriptions. No fluff. Just skills that ship.